Saiba como a IA é realmente construída
Percorra o caminho da areia à máquina pensante, vire os cartões de curiosidades, explore um rack de servidor real e teste os seus conhecimentos. Sem jargão — ative o modo simples a qualquer momento.
A Jornada: da areia à máquina pensante
Dez paradas. Siga o cabo — cada parada passa seu trabalho para a próxima, exatamente como na cadeia de suprimentos real.
 1
Parar 1
Começa como areia
Chips start as melted sand, get printed with light beams finer than a virus, and take three months and a thousand steps to finish.
Leia a história completa →
 2
Parar 2
O sanduíche de memória
HBM is super-fast memory stacked like a tiny sandwich right next to the chip, so the AI can read its own brain fast enough to talk.
Leia a história completa →
 3
Parar 3
Unir chips em um super-chip
When one chip can't be made any bigger, engineers glue several chips together so perfectly they act like one — that gluing is packaging.
Leia a história completa →
 4
Parar 4
Conheça a GPU
A GPU is a chip with thousands of tiny calculators working at once — it was built to draw video games, and it turned out to be perfect for AI.
Leia a história completa →
 5
Parar 5
Ligar 100 000 em conjunto
One computer isn't enough for AI, so special super-fast cables and switches make 100,000 computers act like a single giant one.
Leia a história completa →
 6
Parar 6
Mantenha-o resfriado
New AI chips run so hot that fans can't cool them anymore — so water flows through tiny metal plates bolted right onto the chips.
Leia a história completa →
 7
Parar 7
Alimente-o com gigawatts
Every AI answer costs electricity, and AI is growing so fast that companies are restarting old power plants just to feed it.
Leia a história completa →
 8
Parar 8
Entre no edifício
An AI data center is a giant building full of computer shelves, thick cables, plumbing for coolant, and enough electricity for a whole city.
Leia a história completa →
 9
Parar 9
Treine a máquina
Training an AI means showing it trillions of examples for months while thousands of chips slowly tune billions of little dials.
Leia a história completa →
 10
Parar 10
Faça uma pergunta
When you ask AI a question, it writes the answer one word-piece at a time — each piece is a lightning-fast trip through the whole model.
Leia a história completa →
Explore um rack de verdade
É aqui que a IA realmente vive. Toque nos pontos iluminados para ver o que cada parte faz.
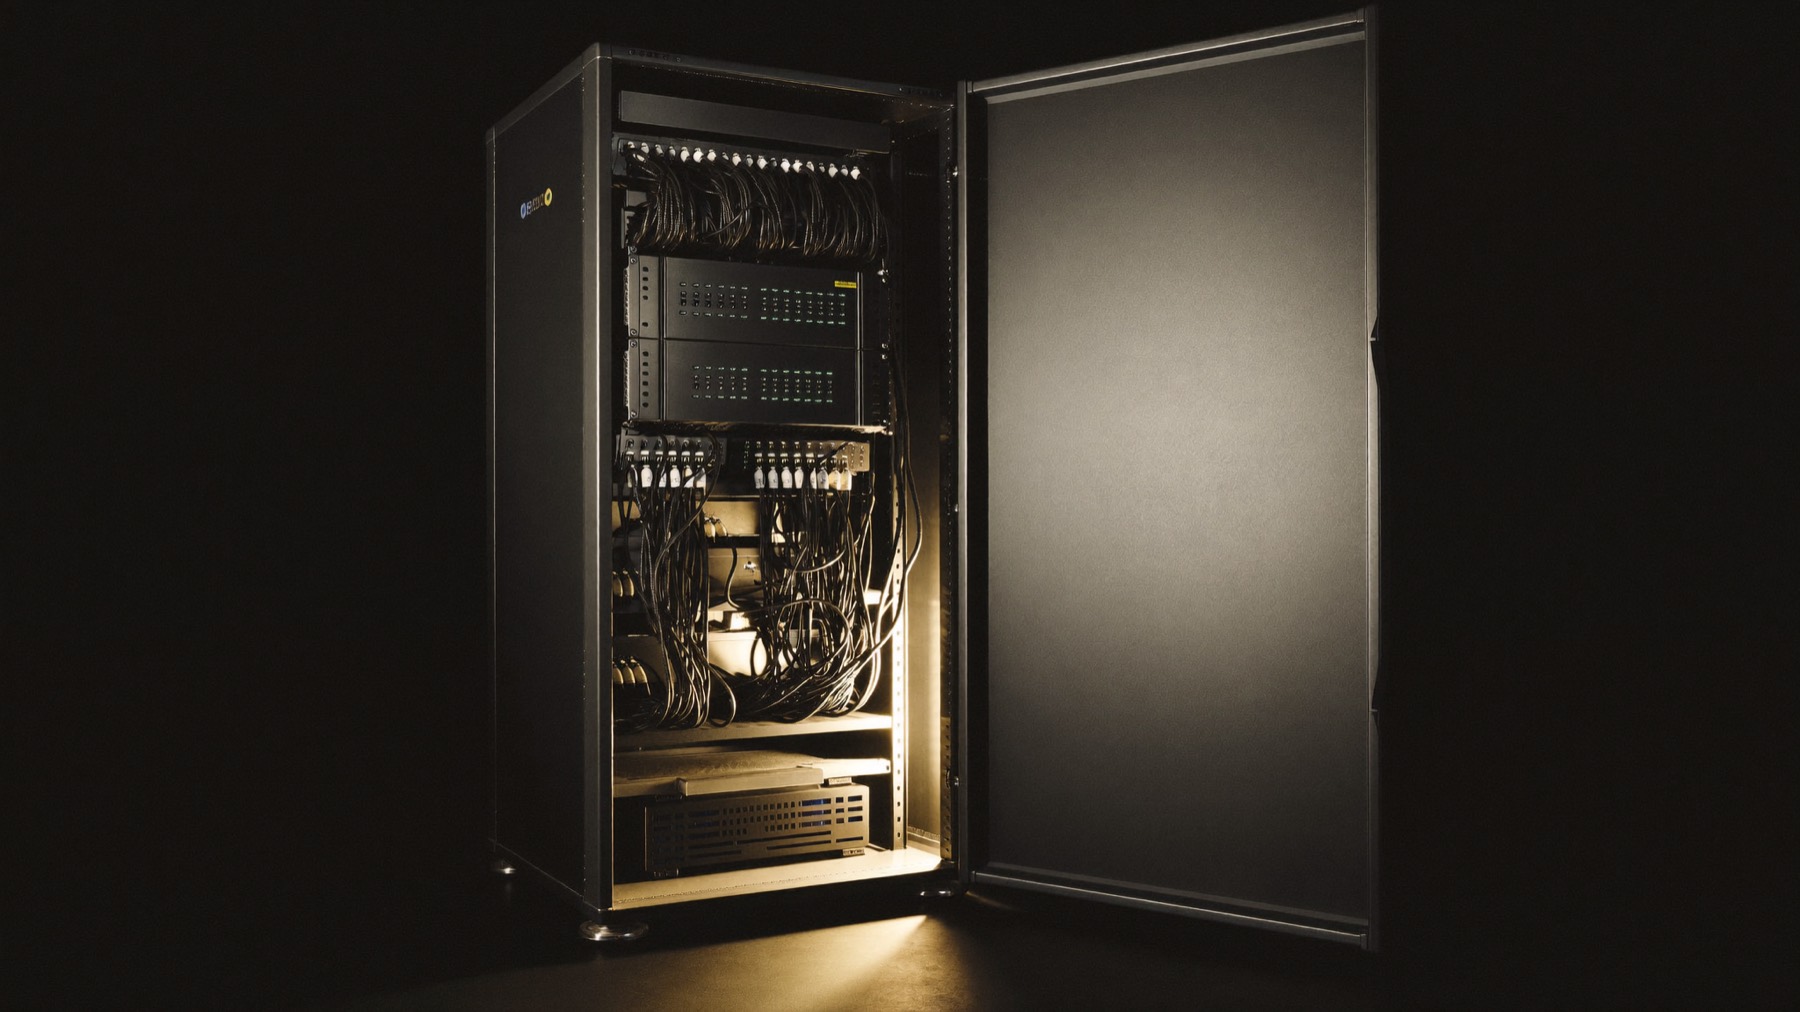
Todas as máquinas se comunicam por meio desses feixes. Em grandes racks de IA, milhares de links de cobre e fibra conectam os servidores em uma só equipe.
Leia a história completa →Os LEDs de status indicam aos engenheiros que cada máquina está ativa — as mesmas luzes piscando na foto da nossa página inicial.
Leia a história completa →Os switches conectam este rack a milhares de outros, para que todos possam processar um problema em conjunto.
Leia a história completa →Eletricidade entra, respostas saem. Um rack de IA moderno pode consumir tanta energia quanto cerca de 100 residências.
Leia a história completa →As fontes de alimentação e os equipamentos mais pesados ficam na parte baixa — e nos novos racks de IA, a tubulação de resfriamento líquido se junta a eles.
Leia a história completa →Você sabia?
Toque em um cartão para virá-lo.
Teste seus conhecimentos
Oito perguntas rápidas. Sem notas, sem pressão — cada resposta ensina algo novo.
A biblioteca completa
25Fundamentos
How Modern AI Actually Works
AI is a giant guessing machine: it read almost everything ever written, and now it guesses the next word so well that it can talk, write and code.
Tokens, weights, attention, training and inference — the whole mechanism in one pass, no math required.
How to Read an AI Chip Spec Sheet
Chip ads throw around huge numbers — this shows you which numbers actually matter, like knowing horsepower from cup holders on a car.
FLOPS, precisions, sparsity footnotes, HBM bandwidth, TDP — what each number means and which ones actually matter.
Training vs Inference: The Two Economies of AI
Training is teaching the AI (slow, done once, super expensive); inference is the AI answering you (fast, happens billions of times a day).
One is a moonshot project, the other is a utility bill — and inference now dominates the buildout.
GPU, TPU, ASIC: What's Actually Different?
A GPU is a chip with thousands of tiny calculators working at once — it was built to draw video games, and it turned out to be perfect for AI.
Why graphics chips run AI, what the custom-silicon crowd changes, and the spectrum from flexible to frozen.
Silicon
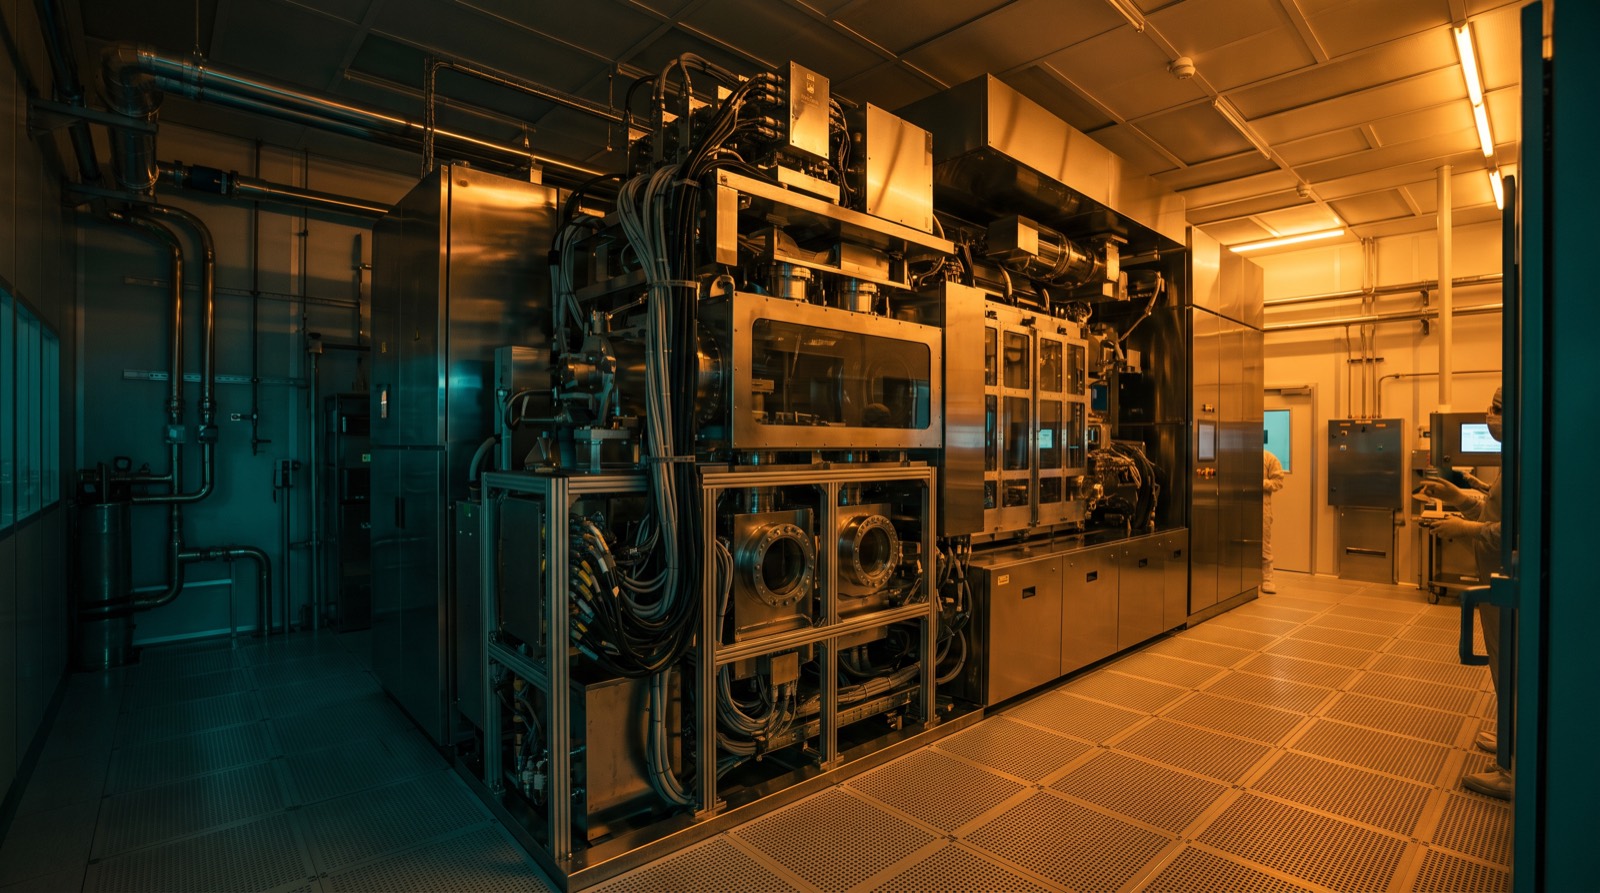
From Sand to Superchip: How AI Chips Are Made
Chips start as melted sand, get printed with light beams finer than a virus, and take three months and a thousand steps to finish.
The 1,000-step journey through a fab — wafers, EUV light, yield, and why only one company can make the machines.
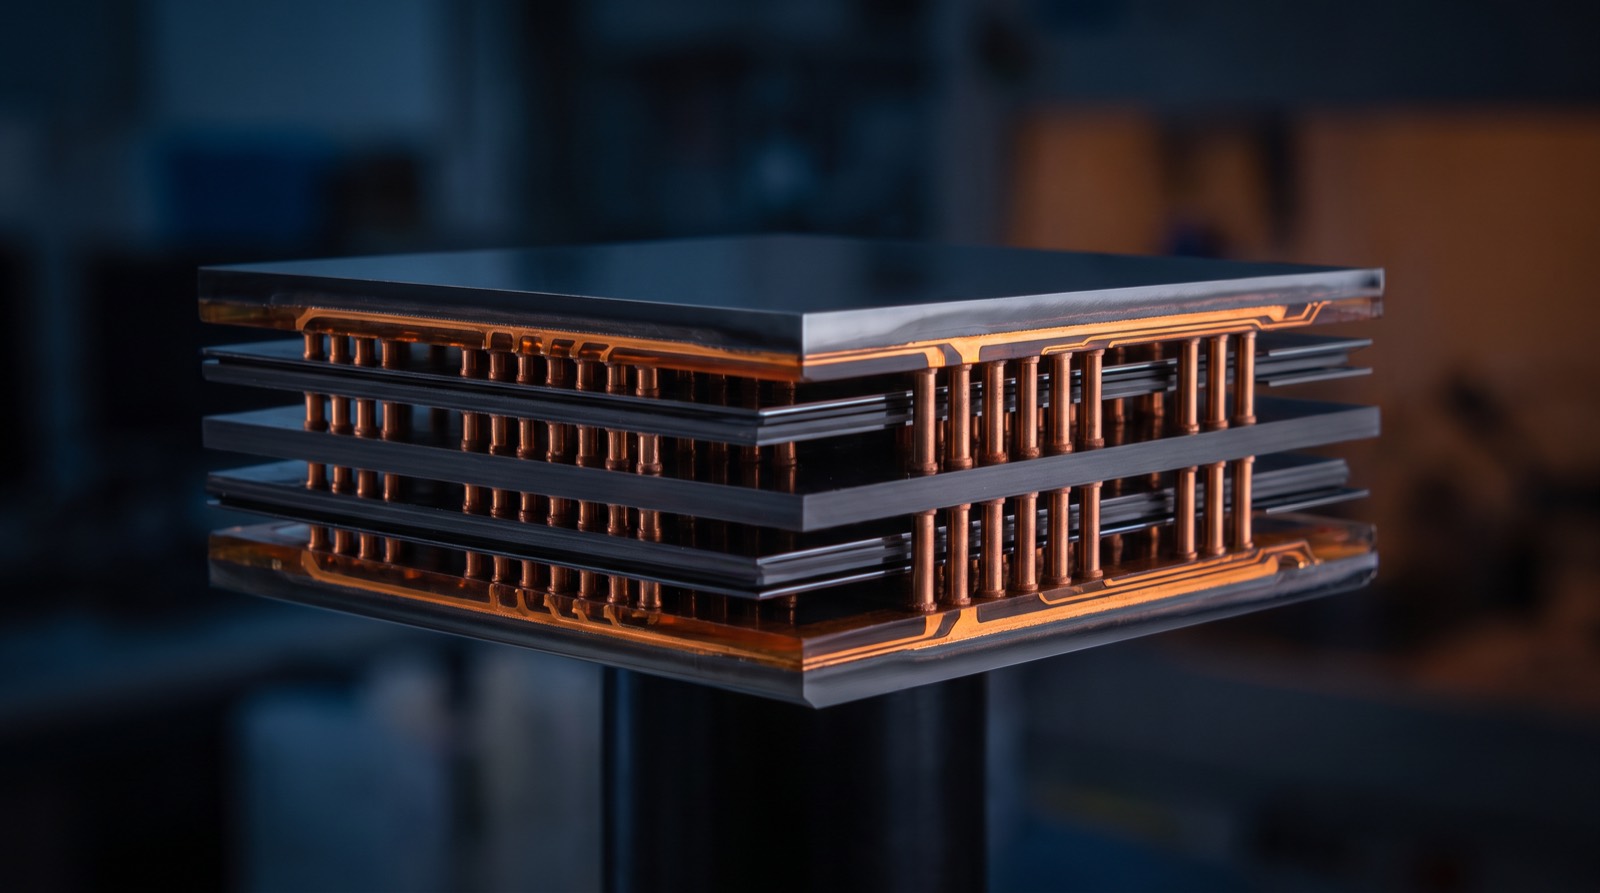
HBM: The Memory That Rations AI
HBM is super-fast memory stacked like a tiny sandwich right next to the chip, so the AI can read its own brain fast enough to talk.
Why stacked memory decides GPU roadmaps, who makes it, and what HBM4 changes.
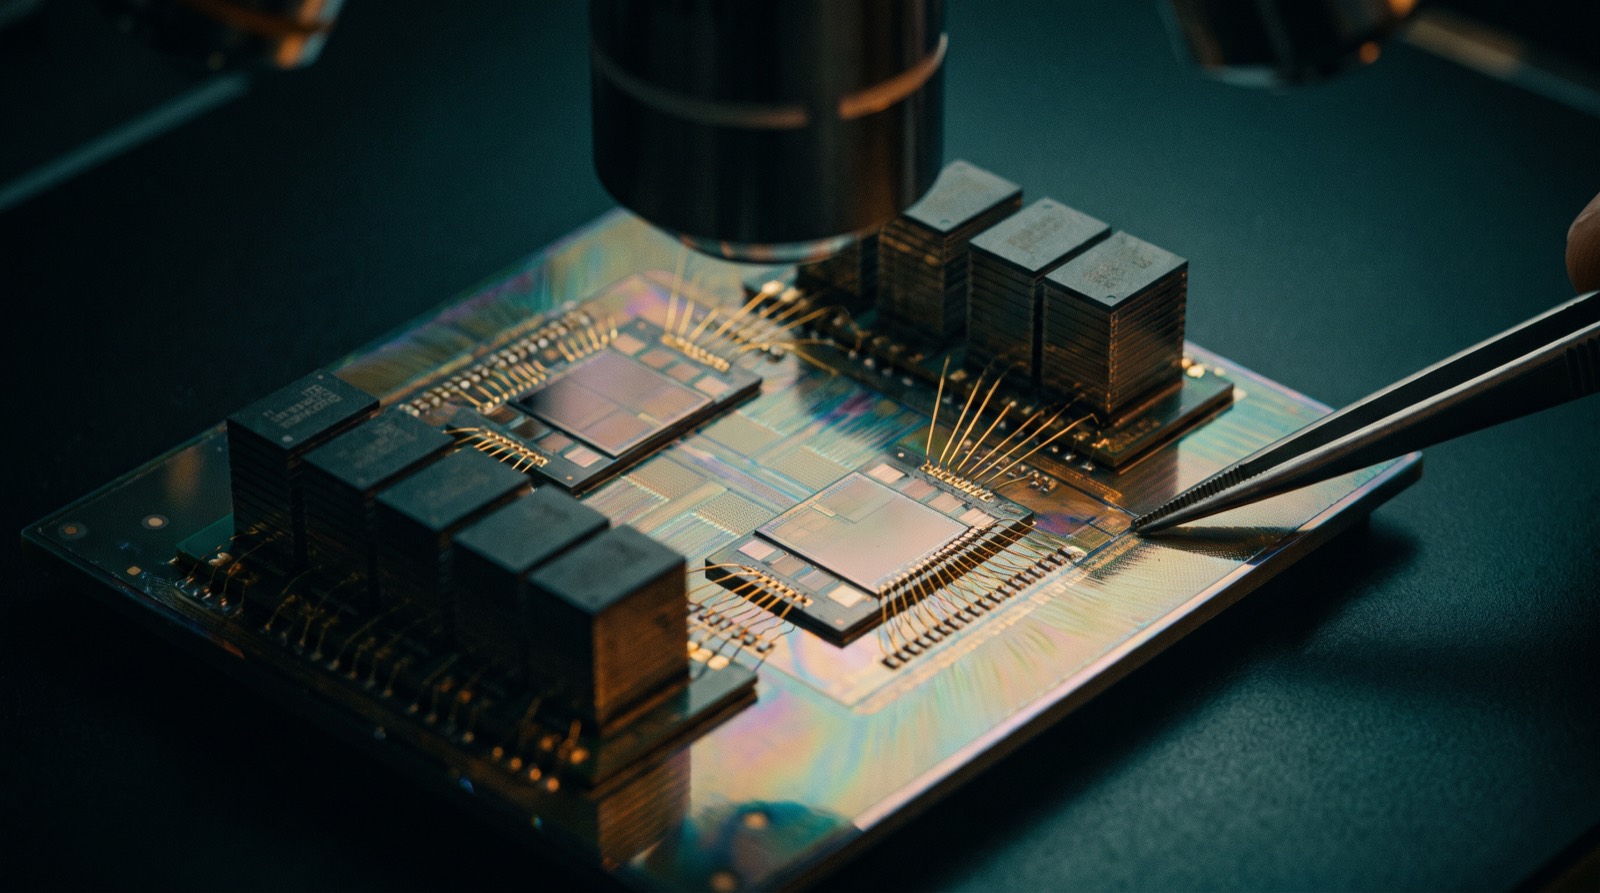
Advanced Packaging: The Bottleneck After the Fab
When one chip can't be made any bigger, engineers glue several chips together so perfectly they act like one — that gluing is packaging.
CoWoS, chiplets and 3D stacking — why assembling chips became as strategic as printing them.
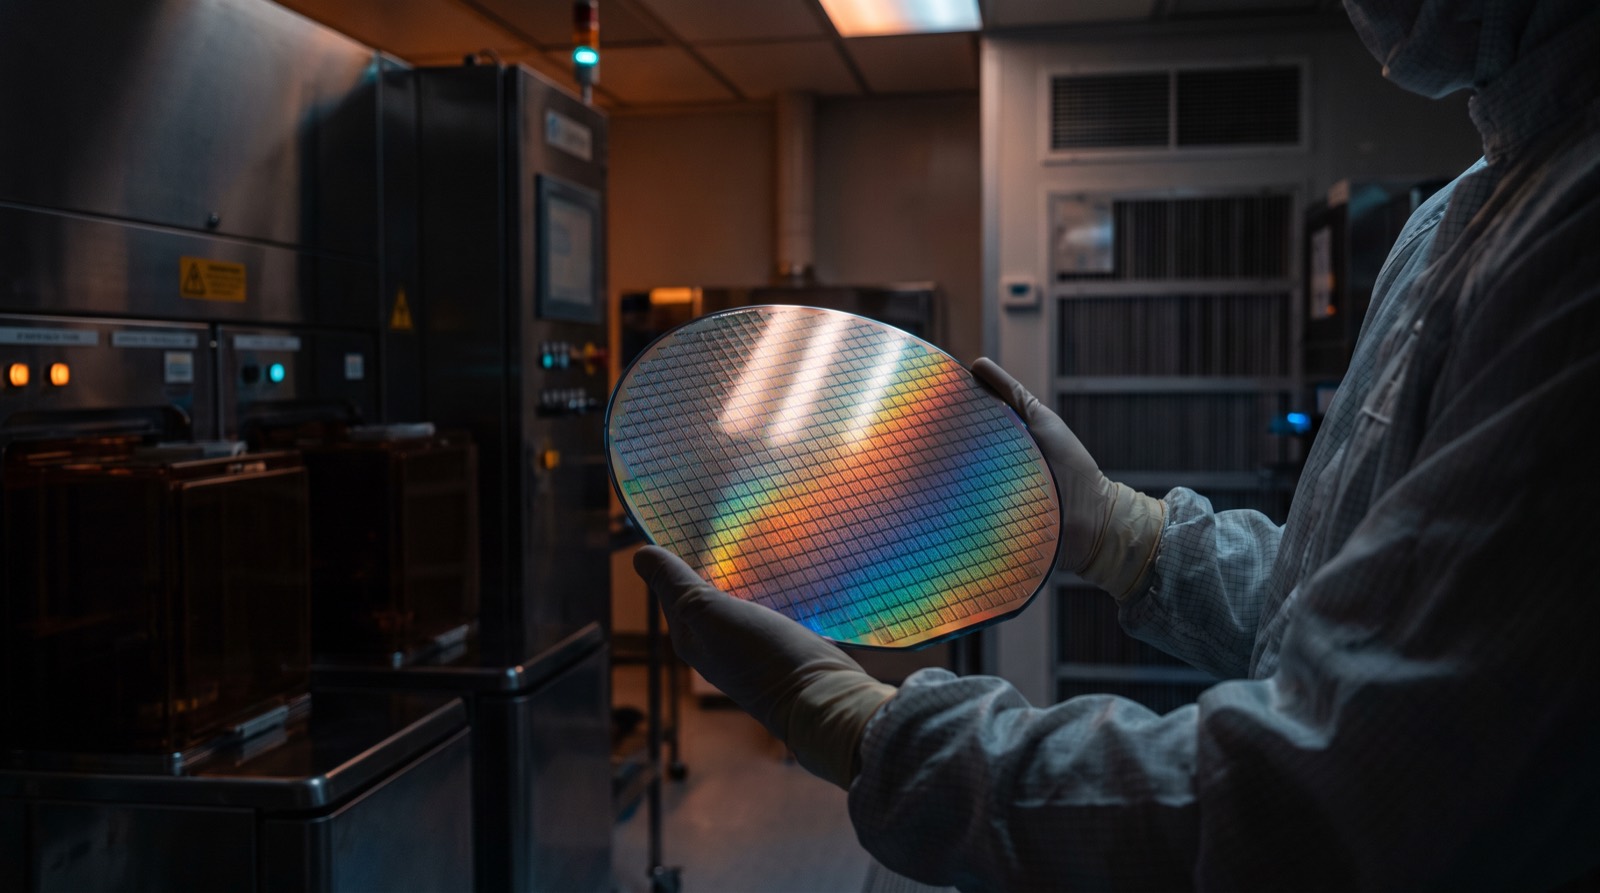
What '3 Nanometers' Actually Means
'3 nanometers' is chip-speak for 'newest and tiniest' — smaller parts mean faster chips that sip less power.
Node names are marketing, density is real, and the roadmap through 2 nm and 18A decides the 2027 chip race.
Sistemas e instalações
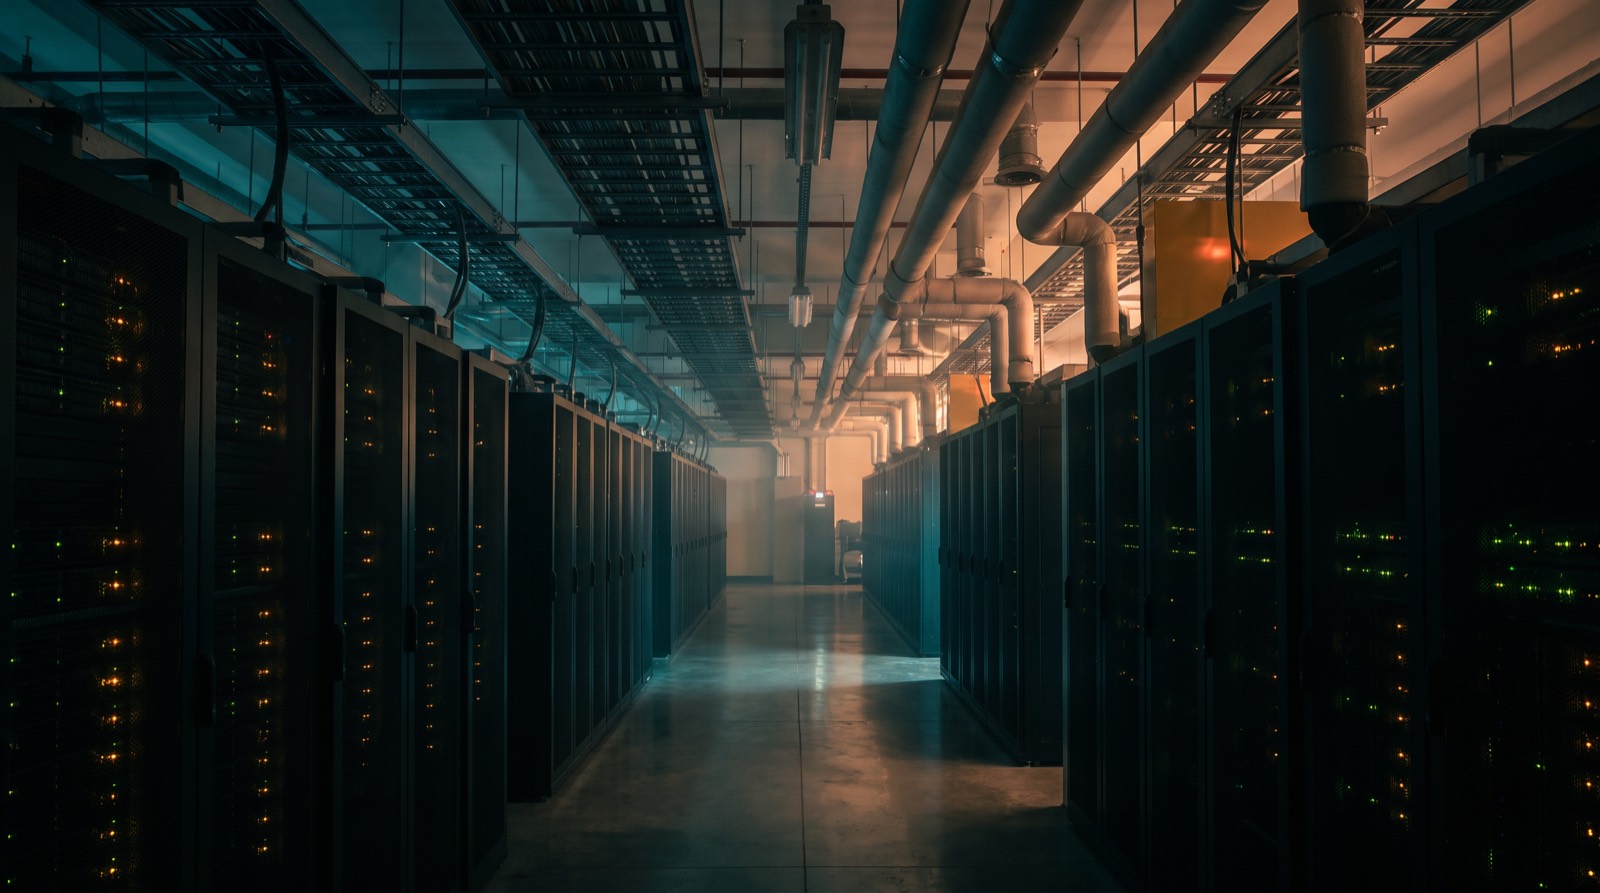
Inside an AI Data Center
An AI data center is a giant building full of computer shelves, thick cables, plumbing for coolant, and enough electricity for a whole city.
A guided tour from the substation to the GPU tray — what's physically inside a modern AI campus.
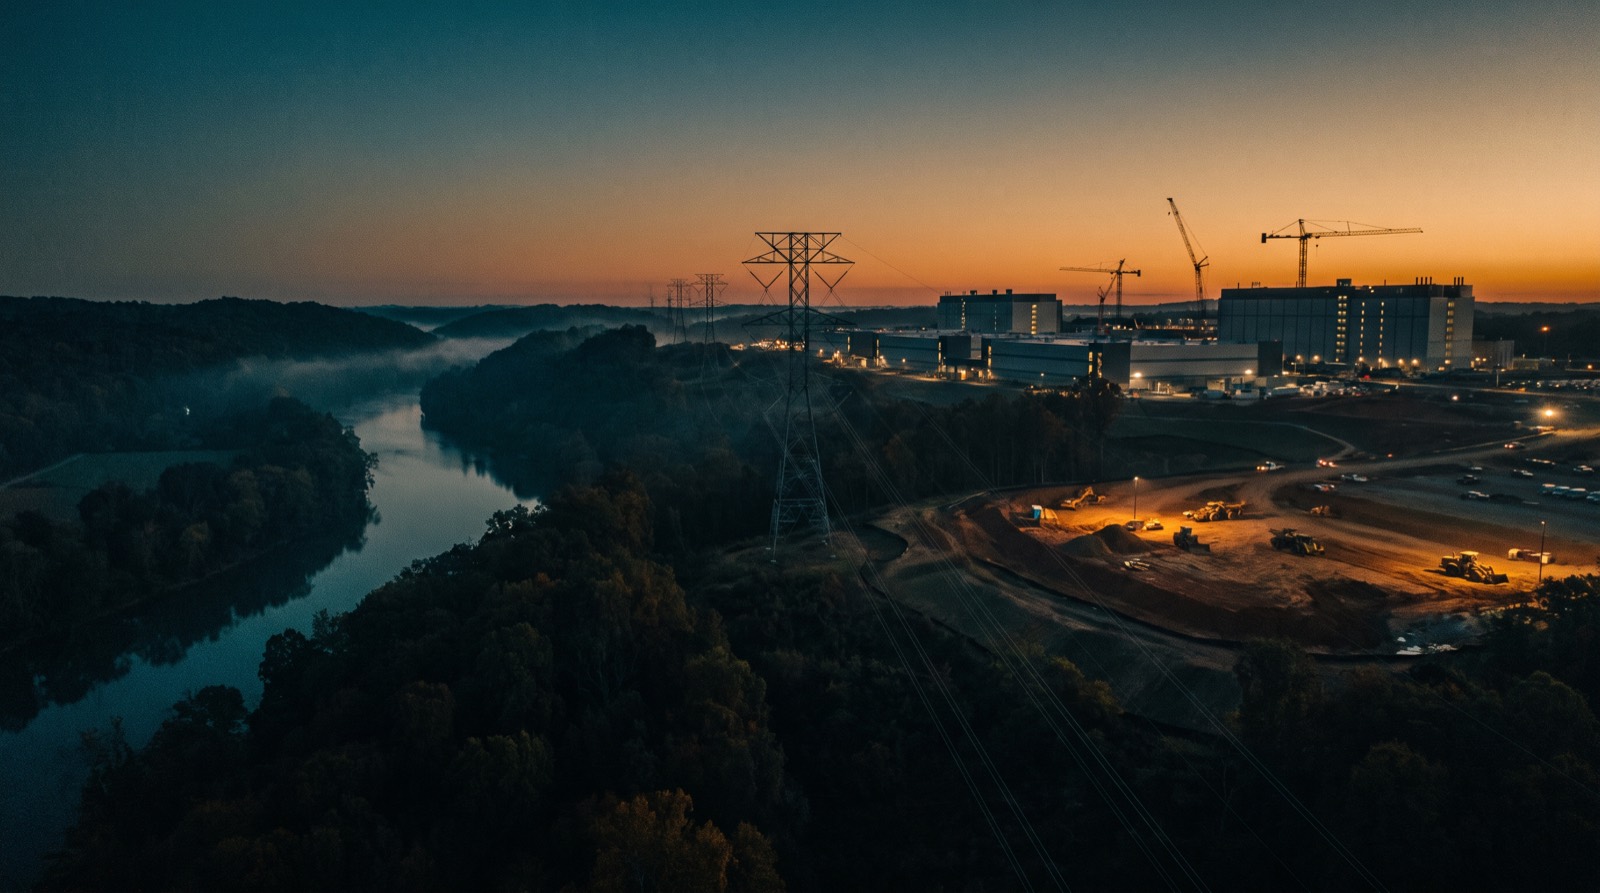
Where Data Centers Go (and Why)
Data centers get built where there's lots of power, water or cooling, and fast internet lines — learn the clues and you can guess where the next one goes.
Read a map like a data-center scout: water, power corridors, fiber, climate and the tells that predict the next AI campus.
Networks: How 100,000 GPUs Become One Computer
One computer isn't enough for AI, so special super-fast cables and switches make 100,000 computers act like a single giant one.
Scale-up vs scale-out, InfiniBand vs Ethernet, and why optics are eating the cluster budget.
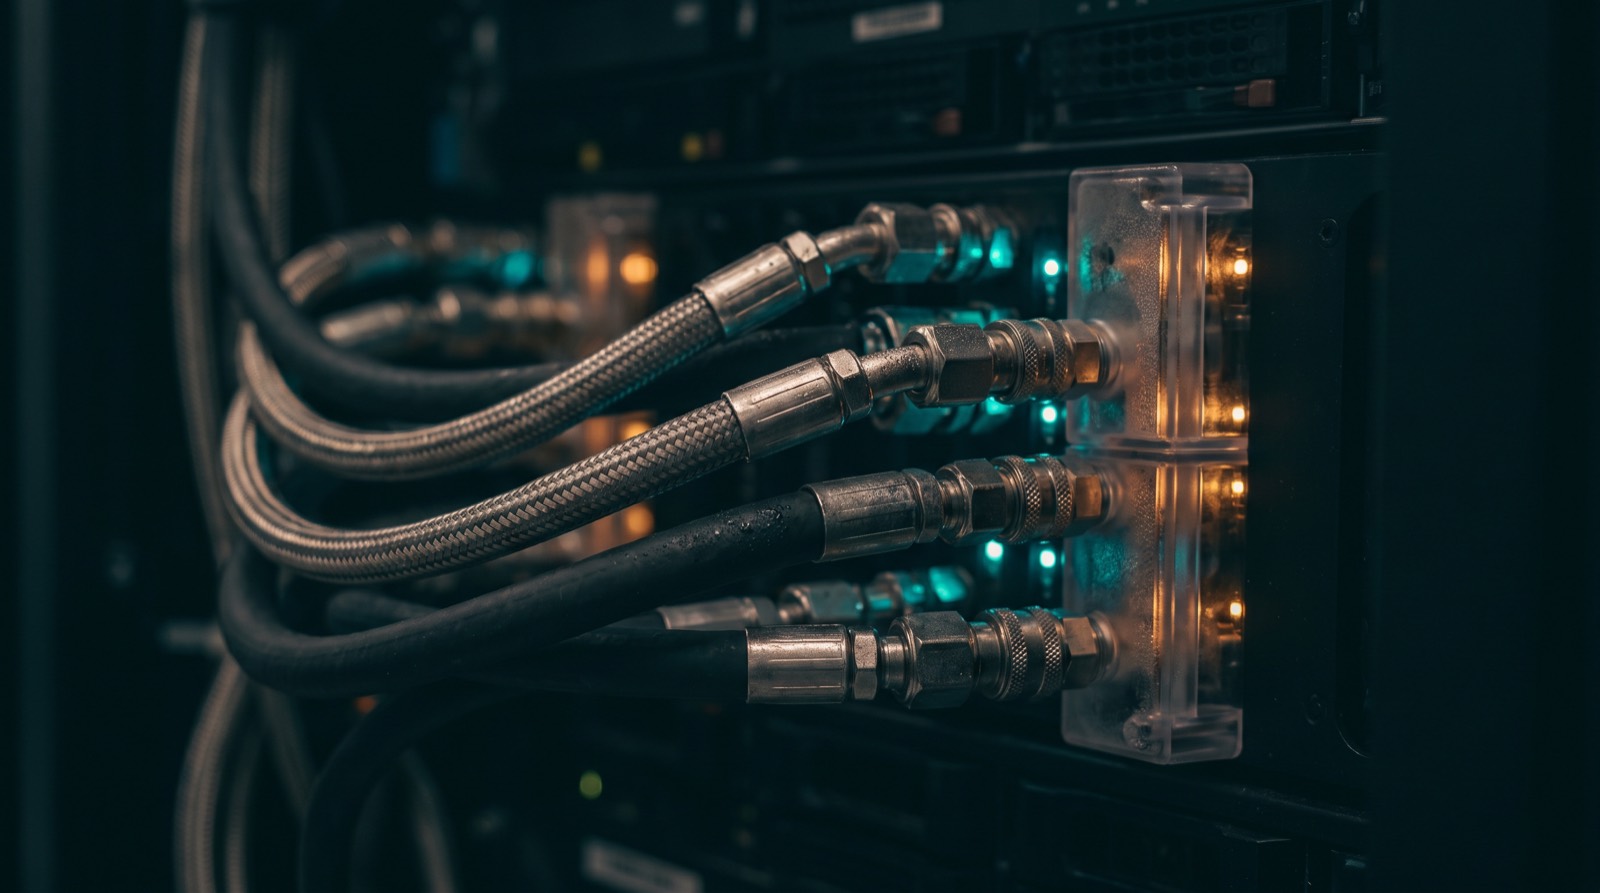
Liquid Cooling: Why AI Got Wet
New AI chips run so hot that fans can't cool them anymore — so water flows through tiny metal plates bolted right onto the chips.
From fans to cold plates to immersion — the thermal transition that rebuilt the data-center industry.
Neoclouds: The GPU Landlords
Neoclouds are companies that buy mountains of AI chips and rent them out by the hour, like a car-rental lot for supercomputers.
CoreWeave, Lambda, Nebius, Crusoe — how GPU-only clouds rose, and the debt-and-contracts machine underneath.
Energia
The Power Problem
Every AI answer costs electricity, and AI is growing so fast that companies are restarting old power plants just to feed it.
How AI met the grid: real demand numbers, the bottlenecks that actually bind, and what's being built about it.
The Nuclear Revival
AI companies need steady power day and night, so they're paying to switch old nuclear plants back on and order new mini-reactors.
Restarts, 20-year PPAs and SMR fleets — what AI money is actually doing to nuclear power, deal by deal.
Interconnection: The Longest Queue in Tech
Building the data center is the easy part — waiting in line to plug it into the power grid can take years longer.
Why plugging in takes longer than building — transformers, studies, and the megawatts stuck in line.
Modelos e software
How a Frontier Model Gets Trained
Training an AI means showing it trillions of examples for months while thousands of chips slowly tune billions of little dials.
Data pipelines, parallelism, failures at 3 a.m. — the industrial reality of a training run.
What Happens When You Hit Enter
When you ask AI a question, it writes the answer one word-piece at a time — each piece is a lightning-fast trip through the whole model.
Prefill, KV cache, batching, speculative decoding — the machinery behind every chat reply.
The CUDA Moat, Explained
CUDA is NVIDIA's special language for talking to its chips — everyone's code is written in it, which is why switching away from NVIDIA is so hard.
Why NVIDIA's real fortress is software — and every credible attempt to tunnel under it.
Open vs Closed: The War Over Weights
Some AIs are like published recipes anyone can copy and change (open); others are secret recipes you can only order from the restaurant (closed).
Llama, DeepSeek and Qwen versus the API labs — strategy, safety and who profits from free models.
Reasoning Models and the Test-Time Era
Newer AIs learned to think before answering — they scribble invisible scratch-work first, and harder questions get more scratch-work.
The 2024–25 capability jump: RL on verifiable rewards, thinking tokens, and the hardware bill for both.
Indústria & Futuros
The Full Supply Chain, Sand to Intelligence
One AI chip needs sand from one place, machines from another, memory from Korea and assembly in Taiwan — a world tour before it computes anything.
Every layer, every chokepoint, one map — the article version of this database's home page.
The Listed AI-Infrastructure Universe
This maps which companies sell the picks and shovels of the AI gold rush — for learning how the money flows, never as advice on what to buy.
How public markets slice the stack — segments, bellwethers and the honest uncertainties. Research only, never advice.
The Chip War, in Plain English
Countries now treat AI chips like superweapons: America limits which chips China can buy, and that one rule reshapes the whole industry.
What the US export controls actually restrict, how China adapted, and how to read each new round.
2030 and Beyond: Scenarios, Not Prophecies
Nobody knows when computers might match humans at most thinking jobs — this collects what the experts actually predict, with names and dates attached.
What the stack looks like in 2030 under each named scenario — and what would falsify each one.
Conteúdo exclusivamente educacional — pesquisa, nunca consultoria. Cada explicação tem links para o banco de dados, para que você possa verificar os registros reais por trás de cada afirmação.