Découvrez comment l'IA est vraiment construite
Suivez le parcours du sable à la machine pensante, retournez les cartes de faits, explorez un vrai rack de serveurs, puis testez-vous. Aucun jargon requis — activez le mode simplifié à tout moment.
Le Parcours : du sable à la machine pensante
Dix étapes. Suivez le câble — chaque étape transmet son travail à la suivante, exactement comme dans la vraie chaîne d'approvisionnement.
 1
Stop 1
Tout commence par du sable
Chips start as melted sand, get printed with light beams finer than a virus, and take three months and a thousand steps to finish.
Lire l'article complet →
 2
Stop 2
Le sandwich mémoire
HBM is super-fast memory stacked like a tiny sandwich right next to the chip, so the AI can read its own brain fast enough to talk.
Lire l'article complet →
 3
Stop 3
Assembler des chips en super-chip
When one chip can't be made any bigger, engineers glue several chips together so perfectly they act like one — that gluing is packaging.
Lire l'article complet →
 4
Stop 4
Rencontrez le GPU
A GPU is a chip with thousands of tiny calculators working at once — it was built to draw video games, and it turned out to be perfect for AI.
Lire l'article complet →
 5
Stop 5
En connecter 100 000 ensemble
One computer isn't enough for AI, so special super-fast cables and switches make 100,000 computers act like a single giant one.
Lire l'article complet →
 6
Stop 6
Maintenir le refroidissement
New AI chips run so hot that fans can't cool them anymore — so water flows through tiny metal plates bolted right onto the chips.
Lire l'article complet →
 7
Stop 7
Alimentez-le en gigawatts
Every AI answer costs electricity, and AI is growing so fast that companies are restarting old power plants just to feed it.
Lire l'article complet →
 8
Stop 8
Entrez dans le bâtiment
An AI data center is a giant building full of computer shelves, thick cables, plumbing for coolant, and enough electricity for a whole city.
Lire l'article complet →
 9
Stop 9
Entraîner la machine
Training an AI means showing it trillions of examples for months while thousands of chips slowly tune billions of little dials.
Lire l'article complet →
 10
Stop 10
Posez-lui une question
When you ask AI a question, it writes the answer one word-piece at a time — each piece is a lightning-fast trip through the whole model.
Lire l'article complet →
Explorer un rack réel
C'est là que l'IA vit réellement. Appuyez sur les points lumineux pour voir le rôle de chaque composant.
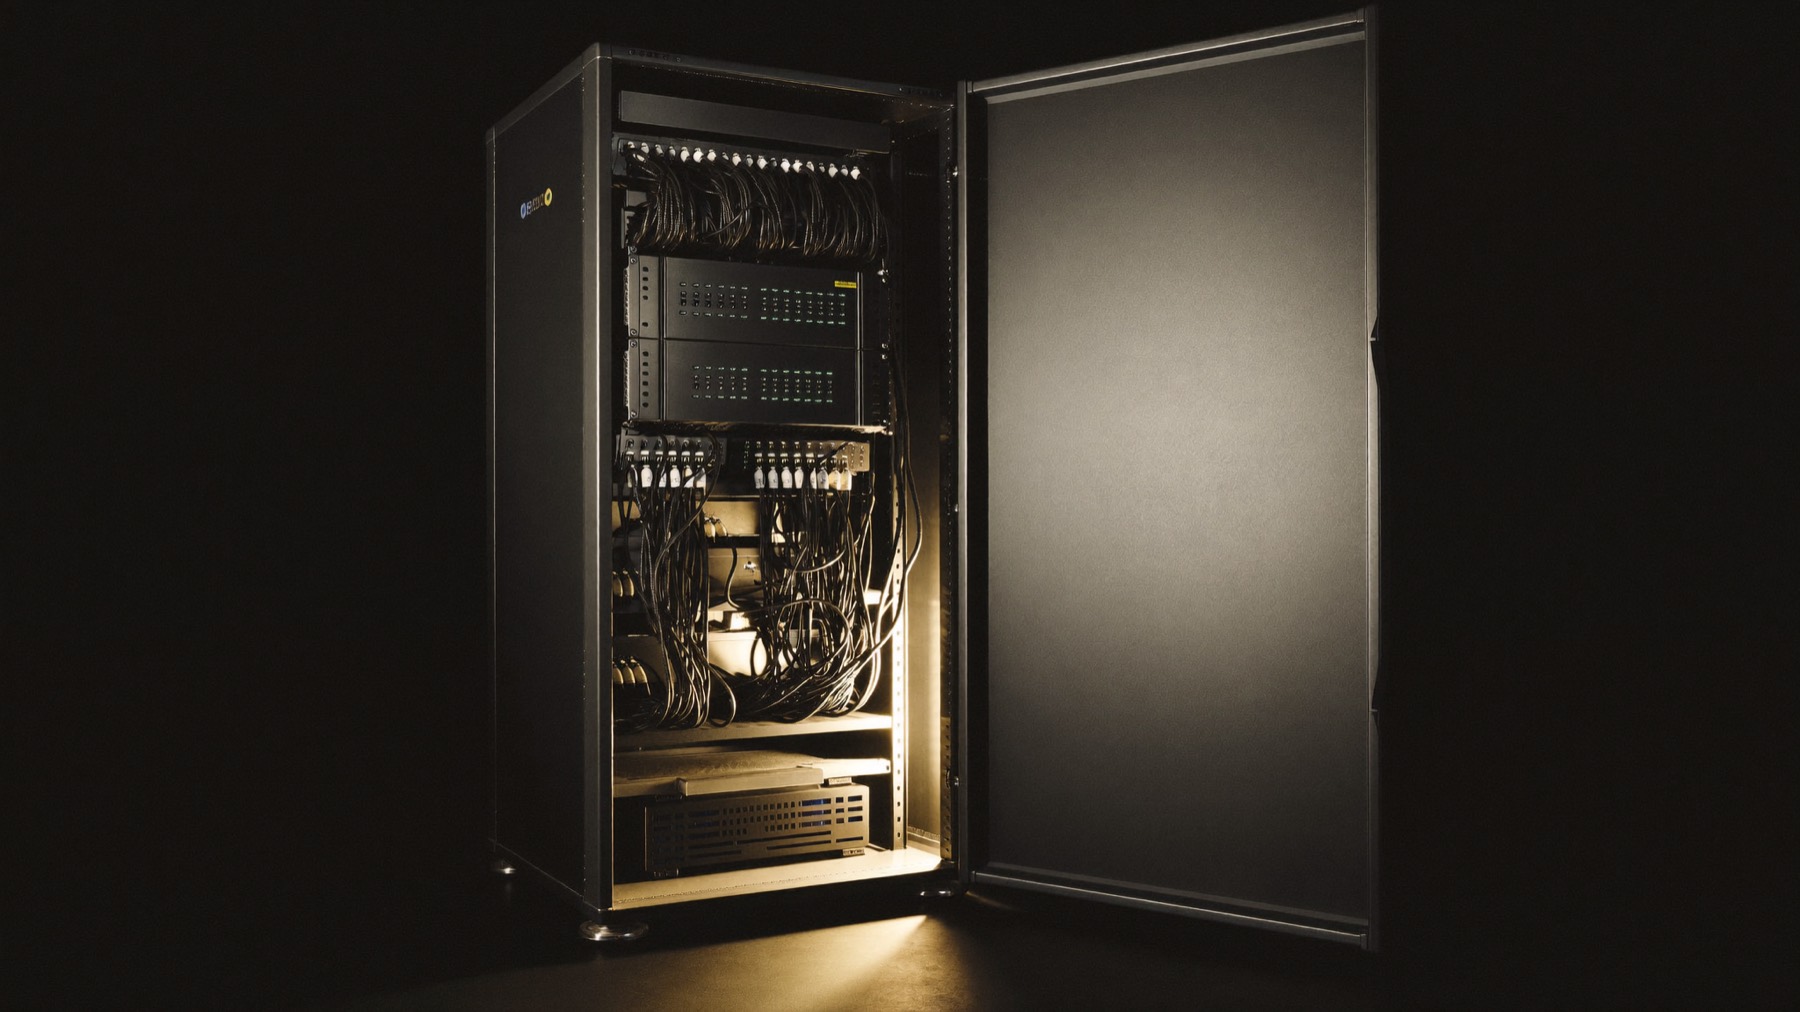
Chaque machine communique via ces faisceaux. Dans les grands racks IA, des milliers de liens en cuivre et en fibre relient les serveurs en une seule équipe.
Lire l'article complet →Les LED de statut indiquent aux ingénieurs que chaque machine est active — ces mêmes petites lumières qui clignotent sur la photo de notre page d'accueil.
Lire l'article complet →Les switches relient ce rack à des milliers d'autres, afin qu'ils puissent tous réfléchir ensemble à un même problème.
Lire l'article complet →De l'électricité en entrée, des réponses en sortie. Un rack IA moderne peut consommer autant d'énergie qu'environ 100 foyers.
Lire l'article complet →Les alimentations électriques et les équipements les plus lourds sont placés en bas — et dans les nouveaux racks IA, la plomberie de refroidissement liquide les rejoint.
Lire l'article complet →Le saviez-vous ?
Appuyez sur une carte pour la retourner.
Testez-vous
Huit questions rapides. Pas de notes, pas de pression — chaque réponse vous apprend quelque chose.
La bibliothèque complète
25Fondements
How Modern AI Actually Works
AI is a giant guessing machine: it read almost everything ever written, and now it guesses the next word so well that it can talk, write and code.
Tokens, weights, attention, training and inference — the whole mechanism in one pass, no math required.
How to Read an AI Chip Spec Sheet
Chip ads throw around huge numbers — this shows you which numbers actually matter, like knowing horsepower from cup holders on a car.
FLOPS, precisions, sparsity footnotes, HBM bandwidth, TDP — what each number means and which ones actually matter.
Training vs Inference: The Two Economies of AI
Training is teaching the AI (slow, done once, super expensive); inference is the AI answering you (fast, happens billions of times a day).
One is a moonshot project, the other is a utility bill — and inference now dominates the buildout.
GPU, TPU, ASIC: What's Actually Different?
A GPU is a chip with thousands of tiny calculators working at once — it was built to draw video games, and it turned out to be perfect for AI.
Why graphics chips run AI, what the custom-silicon crowd changes, and the spectrum from flexible to frozen.
Silicium
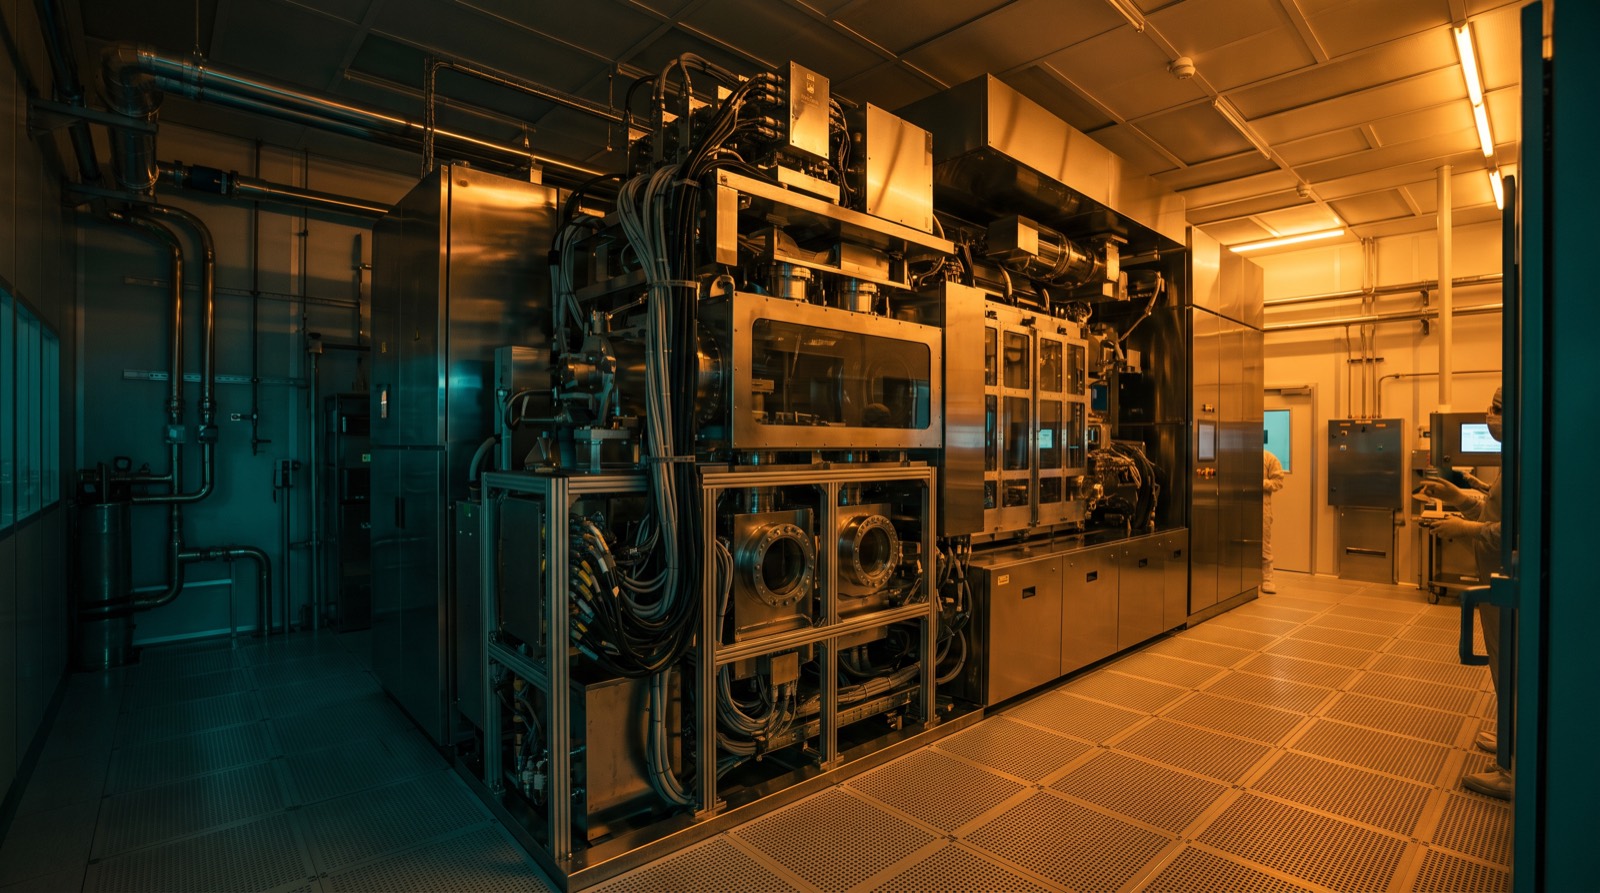
From Sand to Superchip: How AI Chips Are Made
Chips start as melted sand, get printed with light beams finer than a virus, and take three months and a thousand steps to finish.
The 1,000-step journey through a fab — wafers, EUV light, yield, and why only one company can make the machines.
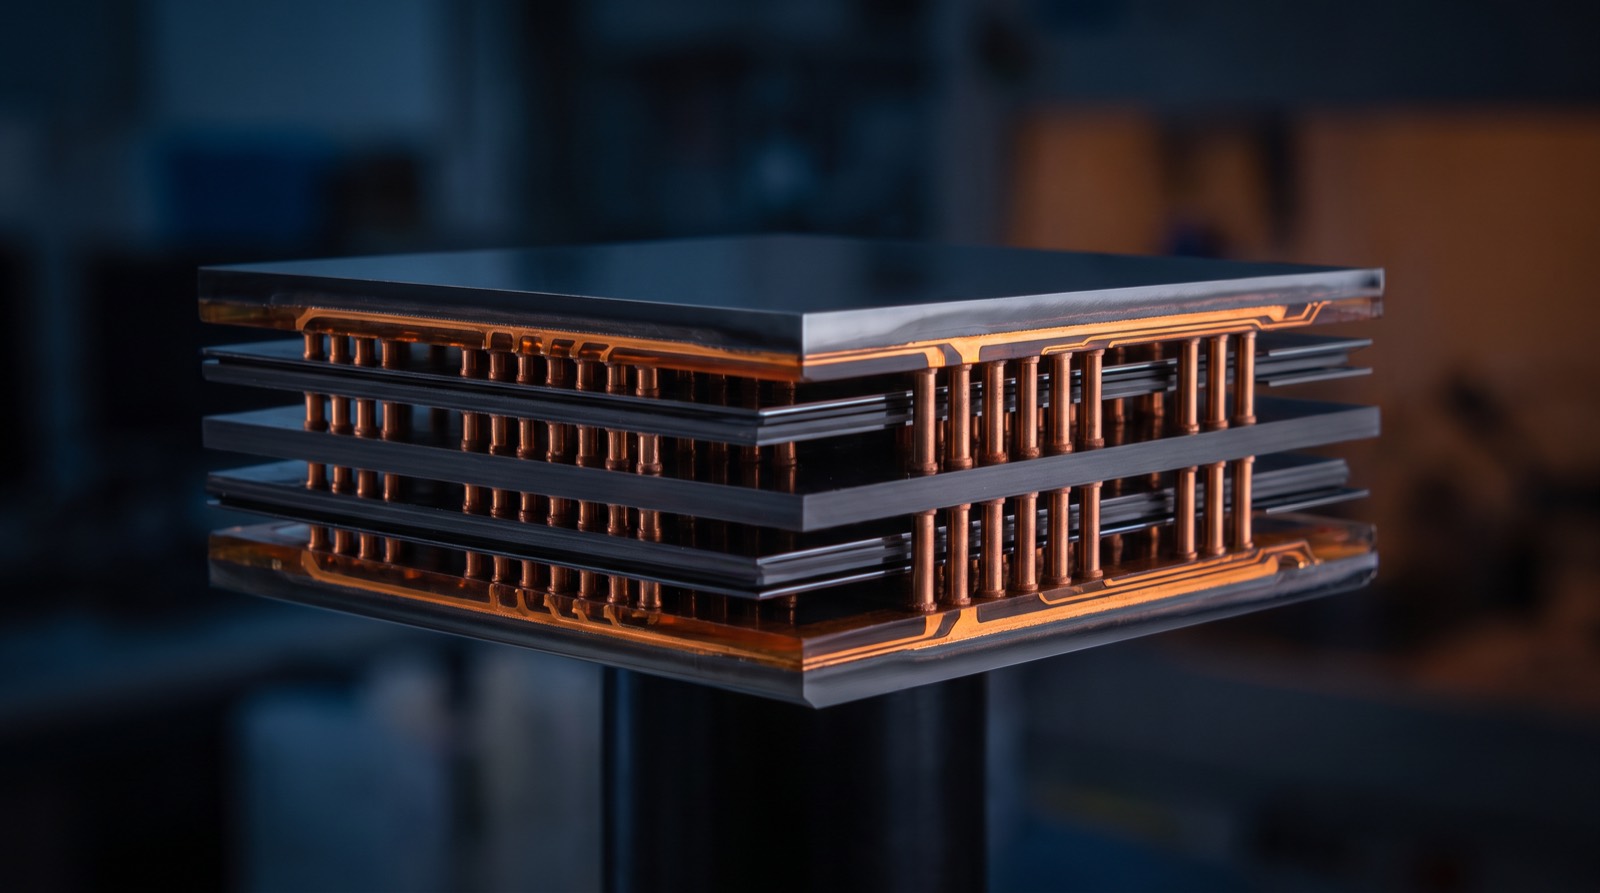
HBM: The Memory That Rations AI
HBM is super-fast memory stacked like a tiny sandwich right next to the chip, so the AI can read its own brain fast enough to talk.
Why stacked memory decides GPU roadmaps, who makes it, and what HBM4 changes.
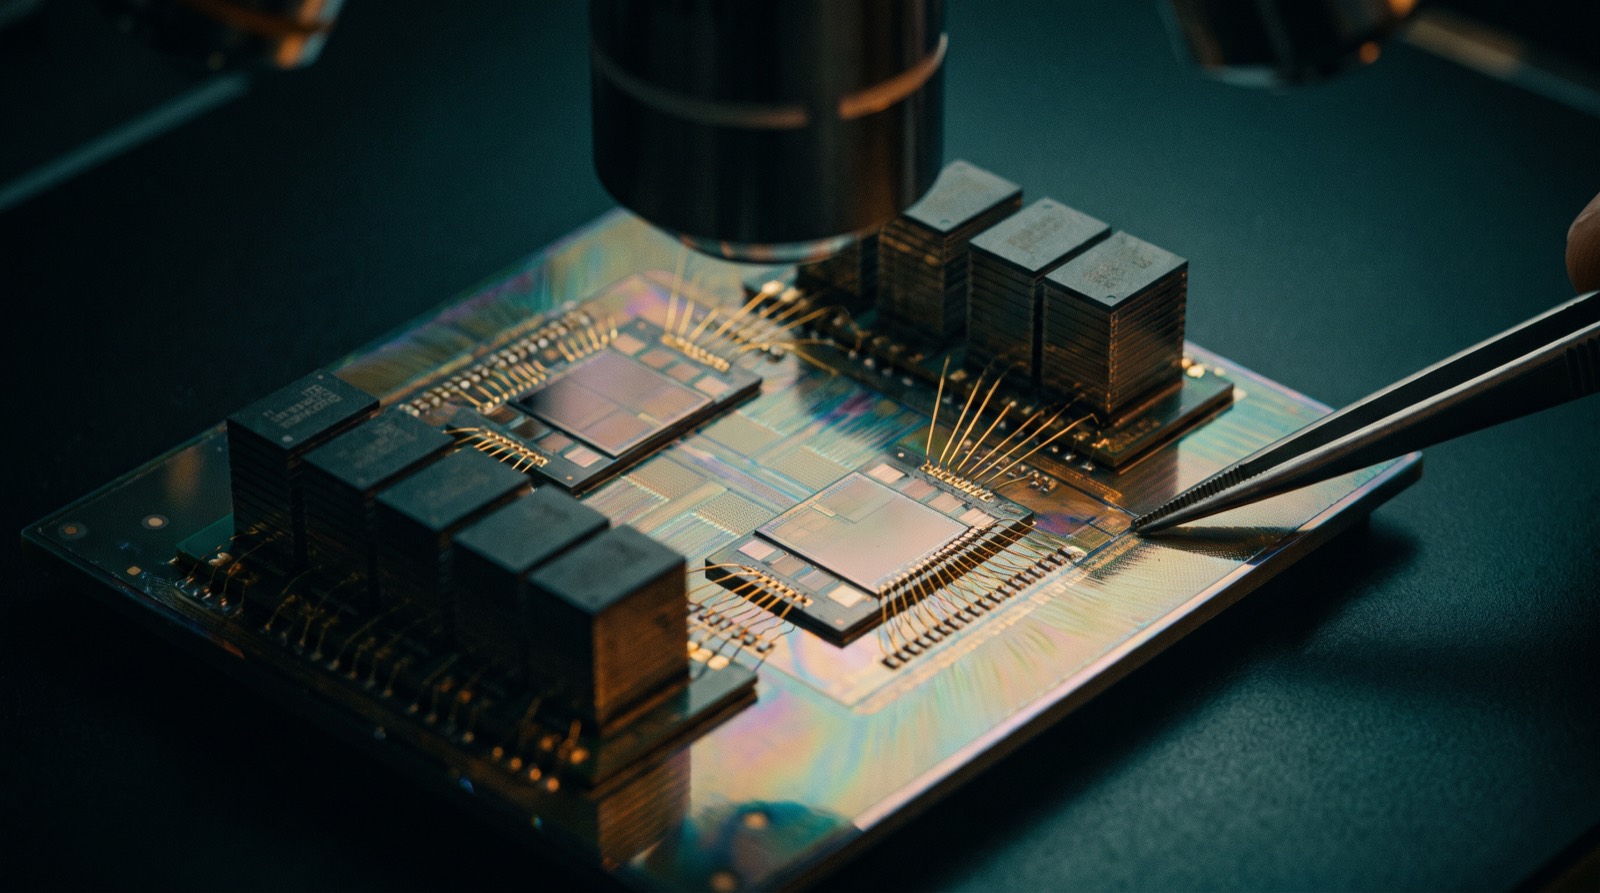
Advanced Packaging: The Bottleneck After the Fab
When one chip can't be made any bigger, engineers glue several chips together so perfectly they act like one — that gluing is packaging.
CoWoS, chiplets and 3D stacking — why assembling chips became as strategic as printing them.
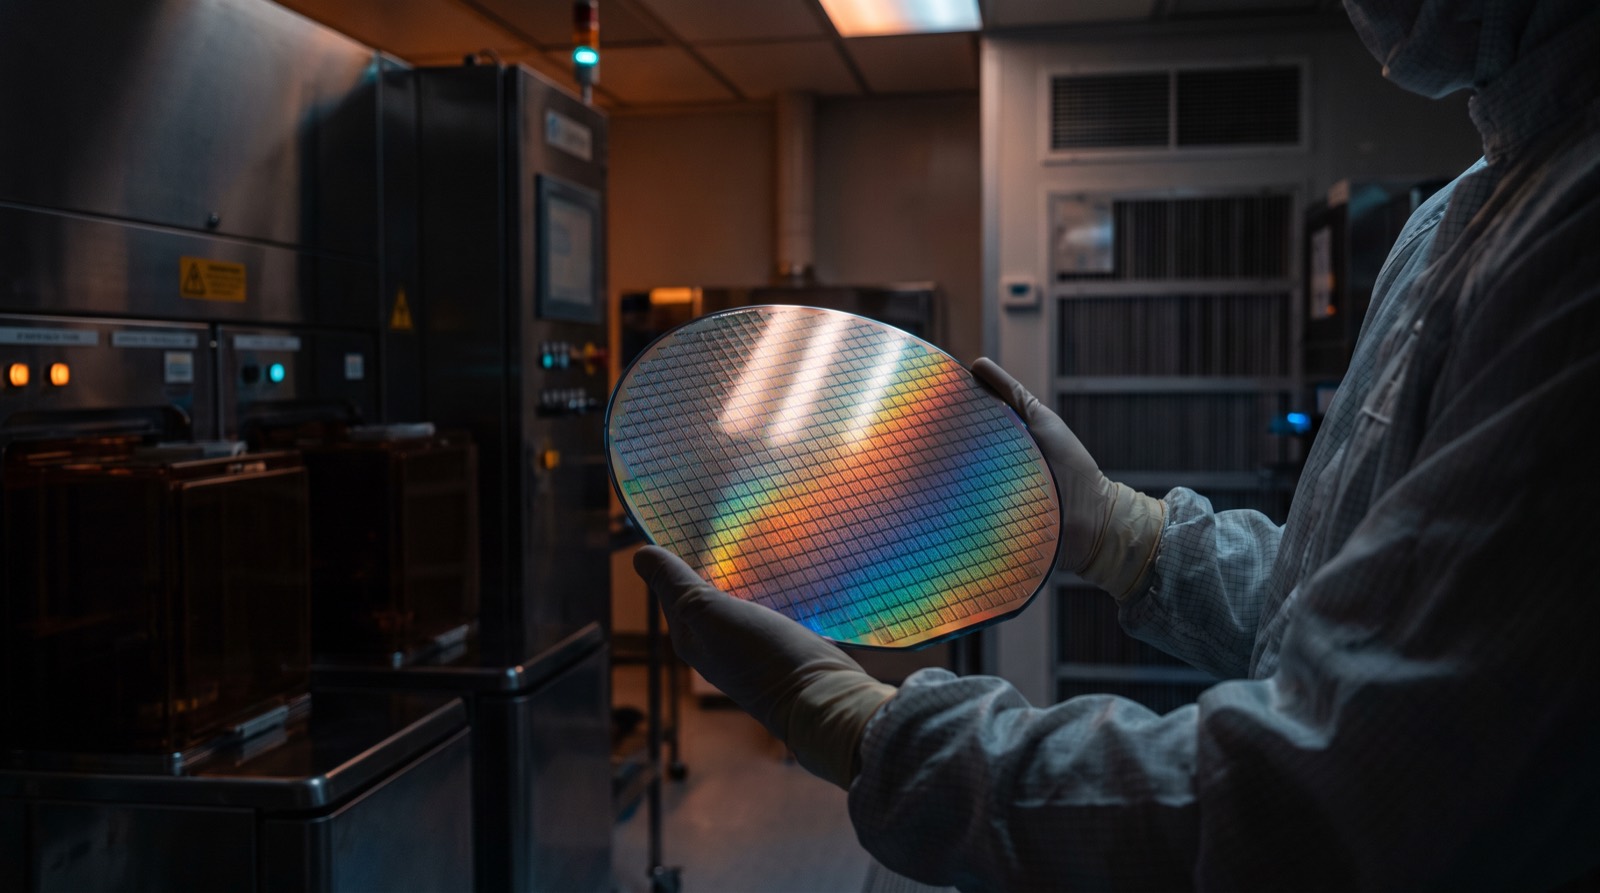
What '3 Nanometers' Actually Means
'3 nanometers' is chip-speak for 'newest and tiniest' — smaller parts mean faster chips that sip less power.
Node names are marketing, density is real, and the roadmap through 2 nm and 18A decides the 2027 chip race.
Systèmes et infrastructures
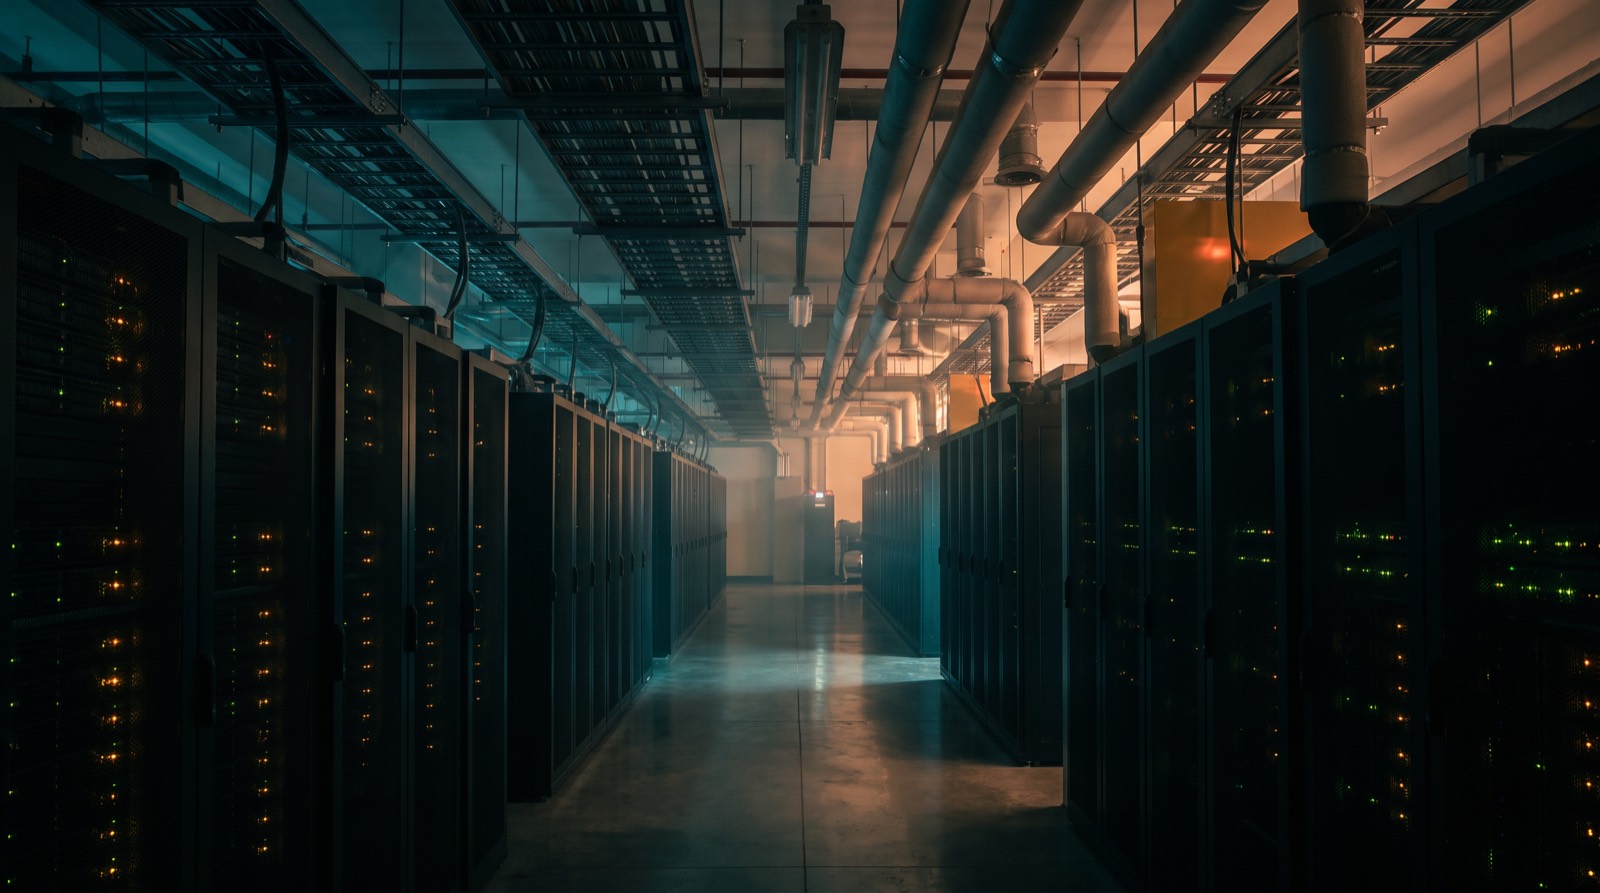
Inside an AI Data Center
An AI data center is a giant building full of computer shelves, thick cables, plumbing for coolant, and enough electricity for a whole city.
A guided tour from the substation to the GPU tray — what's physically inside a modern AI campus.
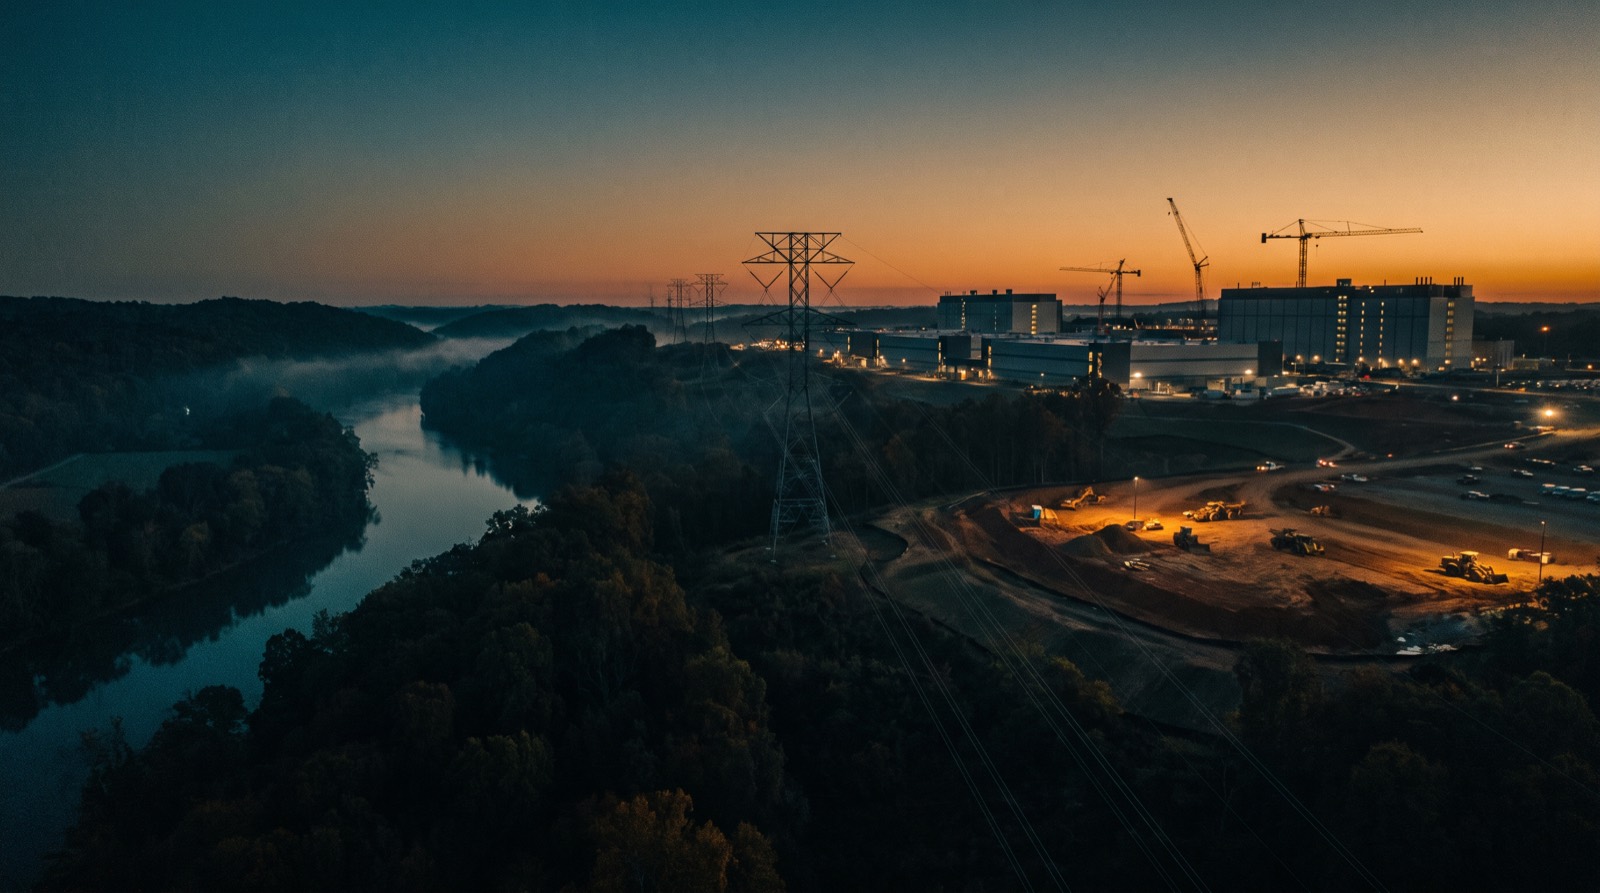
Where Data Centers Go (and Why)
Data centers get built where there's lots of power, water or cooling, and fast internet lines — learn the clues and you can guess where the next one goes.
Read a map like a data-center scout: water, power corridors, fiber, climate and the tells that predict the next AI campus.
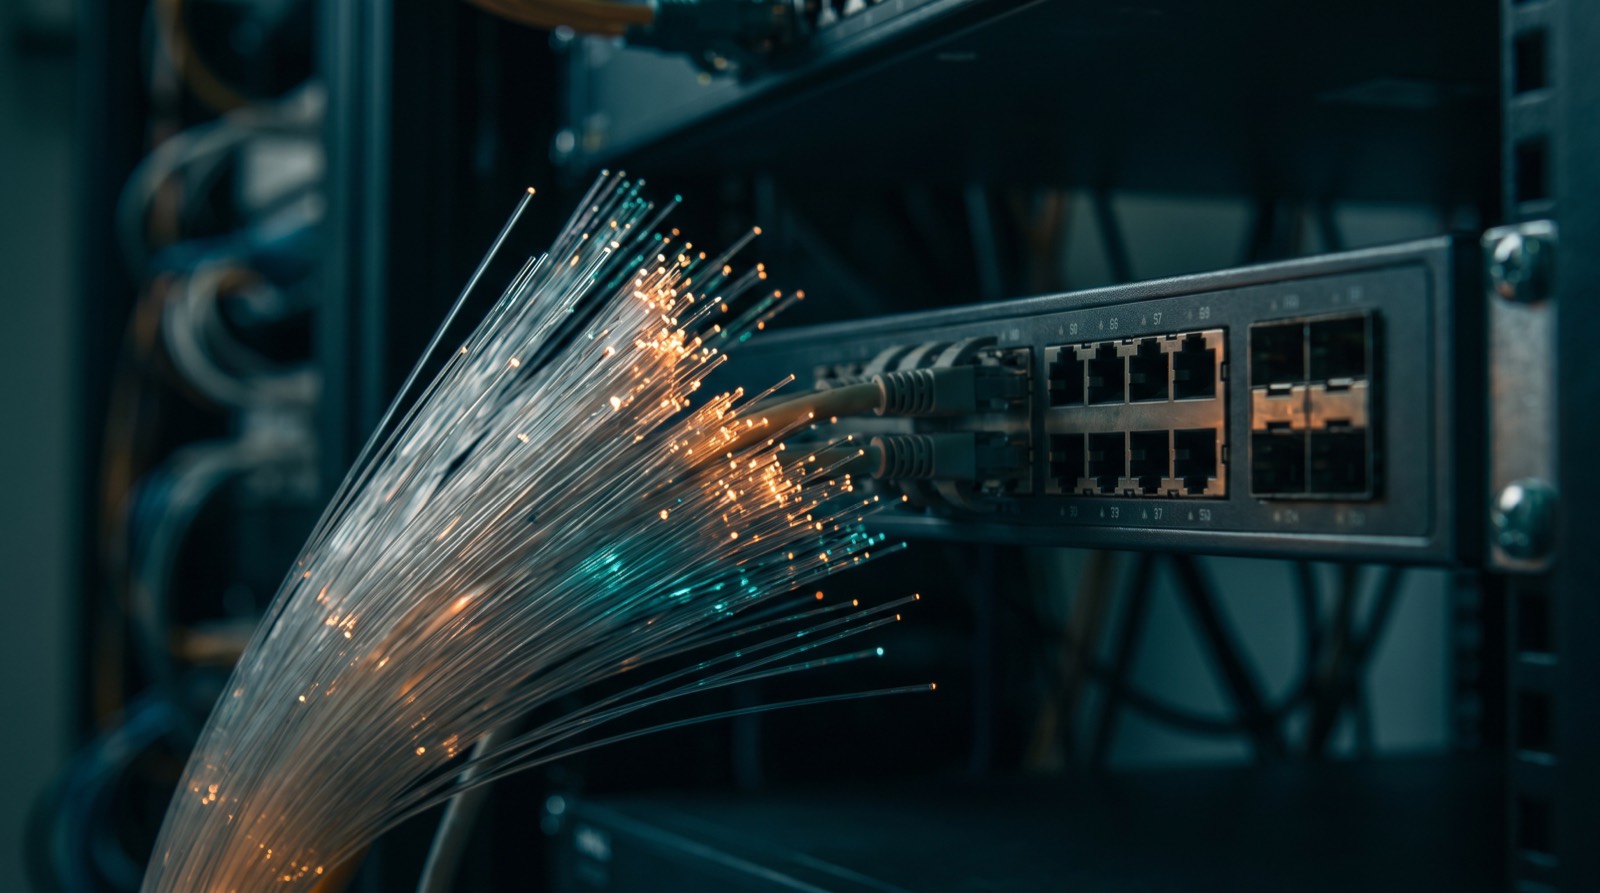
Networks: How 100,000 GPUs Become One Computer
One computer isn't enough for AI, so special super-fast cables and switches make 100,000 computers act like a single giant one.
Scale-up vs scale-out, InfiniBand vs Ethernet, and why optics are eating the cluster budget.
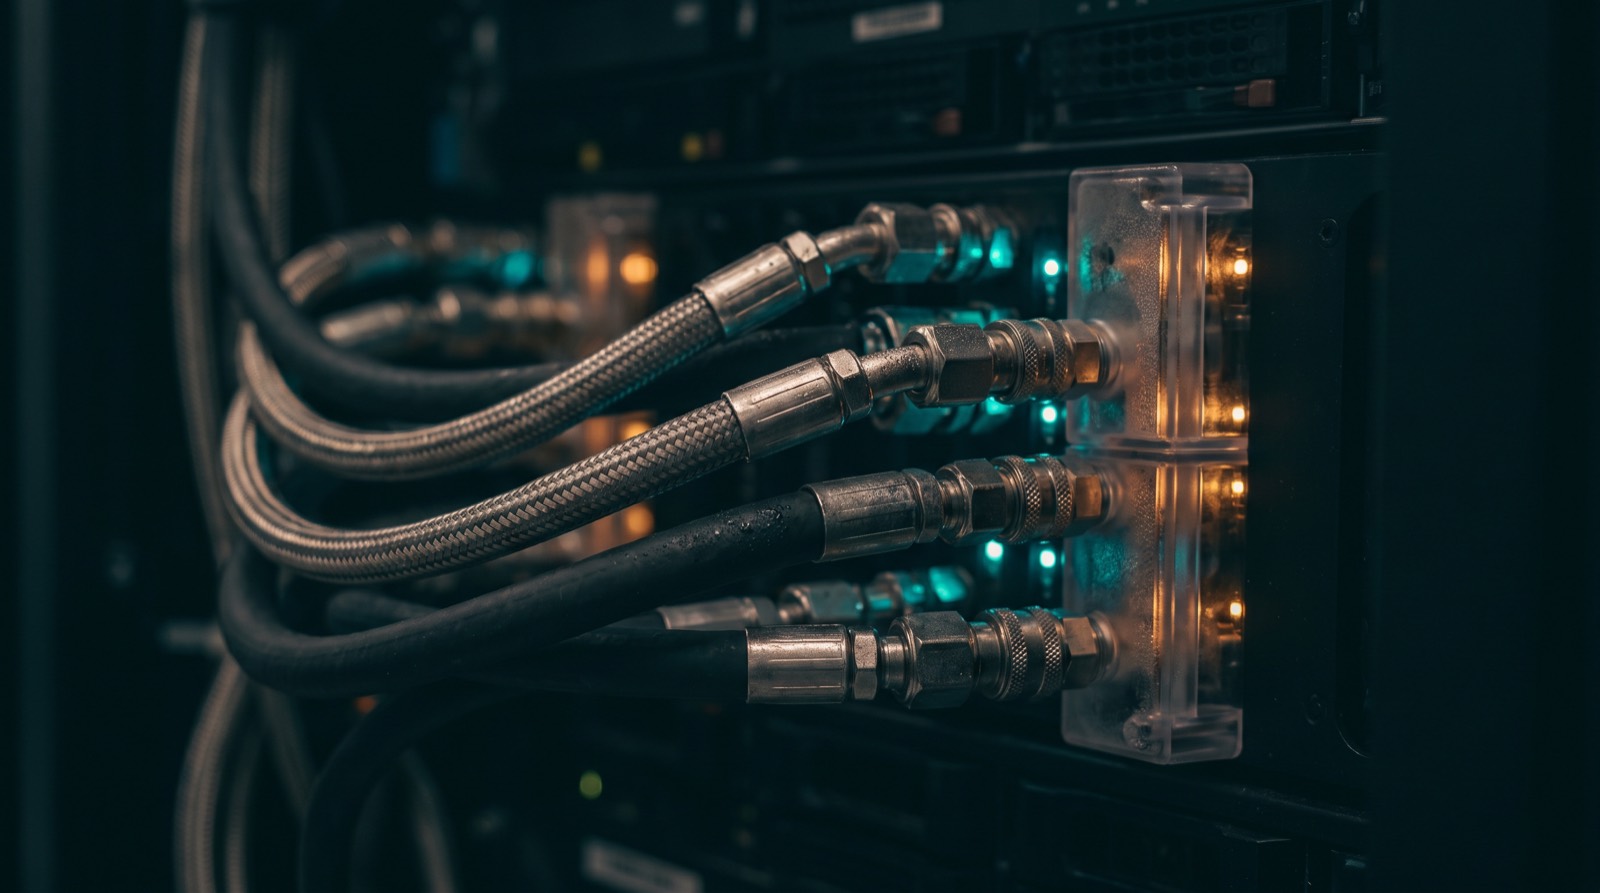
Liquid Cooling: Why AI Got Wet
New AI chips run so hot that fans can't cool them anymore — so water flows through tiny metal plates bolted right onto the chips.
From fans to cold plates to immersion — the thermal transition that rebuilt the data-center industry.
Neoclouds: The GPU Landlords
Neoclouds are companies that buy mountains of AI chips and rent them out by the hour, like a car-rental lot for supercomputers.
CoreWeave, Lambda, Nebius, Crusoe — how GPU-only clouds rose, and the debt-and-contracts machine underneath.
Alimentation
The Power Problem
Every AI answer costs electricity, and AI is growing so fast that companies are restarting old power plants just to feed it.
How AI met the grid: real demand numbers, the bottlenecks that actually bind, and what's being built about it.
The Nuclear Revival
AI companies need steady power day and night, so they're paying to switch old nuclear plants back on and order new mini-reactors.
Restarts, 20-year PPAs and SMR fleets — what AI money is actually doing to nuclear power, deal by deal.
Interconnection: The Longest Queue in Tech
Building the data center is the easy part — waiting in line to plug it into the power grid can take years longer.
Why plugging in takes longer than building — transformers, studies, and the megawatts stuck in line.
Modèles & logiciels
How a Frontier Model Gets Trained
Training an AI means showing it trillions of examples for months while thousands of chips slowly tune billions of little dials.
Data pipelines, parallelism, failures at 3 a.m. — the industrial reality of a training run.
What Happens When You Hit Enter
When you ask AI a question, it writes the answer one word-piece at a time — each piece is a lightning-fast trip through the whole model.
Prefill, KV cache, batching, speculative decoding — the machinery behind every chat reply.
The CUDA Moat, Explained
CUDA is NVIDIA's special language for talking to its chips — everyone's code is written in it, which is why switching away from NVIDIA is so hard.
Why NVIDIA's real fortress is software — and every credible attempt to tunnel under it.
Open vs Closed: The War Over Weights
Some AIs are like published recipes anyone can copy and change (open); others are secret recipes you can only order from the restaurant (closed).
Llama, DeepSeek and Qwen versus the API labs — strategy, safety and who profits from free models.
Reasoning Models and the Test-Time Era
Newer AIs learned to think before answering — they scribble invisible scratch-work first, and harder questions get more scratch-work.
The 2024–25 capability jump: RL on verifiable rewards, thinking tokens, and the hardware bill for both.
Secteur & perspectives
The Full Supply Chain, Sand to Intelligence
One AI chip needs sand from one place, machines from another, memory from Korea and assembly in Taiwan — a world tour before it computes anything.
Every layer, every chokepoint, one map — the article version of this database's home page.
The Listed AI-Infrastructure Universe
This maps which companies sell the picks and shovels of the AI gold rush — for learning how the money flows, never as advice on what to buy.
How public markets slice the stack — segments, bellwethers and the honest uncertainties. Research only, never advice.
The Chip War, in Plain English
Countries now treat AI chips like superweapons: America limits which chips China can buy, and that one rule reshapes the whole industry.
What the US export controls actually restrict, how China adapted, and how to read each new round.
2030 and Beyond: Scenarios, Not Prophecies
Nobody knows when computers might match humans at most thinking jobs — this collects what the experts actually predict, with names and dates attached.
What the stack looks like in 2030 under each named scenario — and what would falsify each one.
Contenu purement éducatif — recherche, jamais de conseils. Chaque article explicatif renvoie à la base de données pour que vous puissiez vérifier les données réelles derrière chaque affirmation.