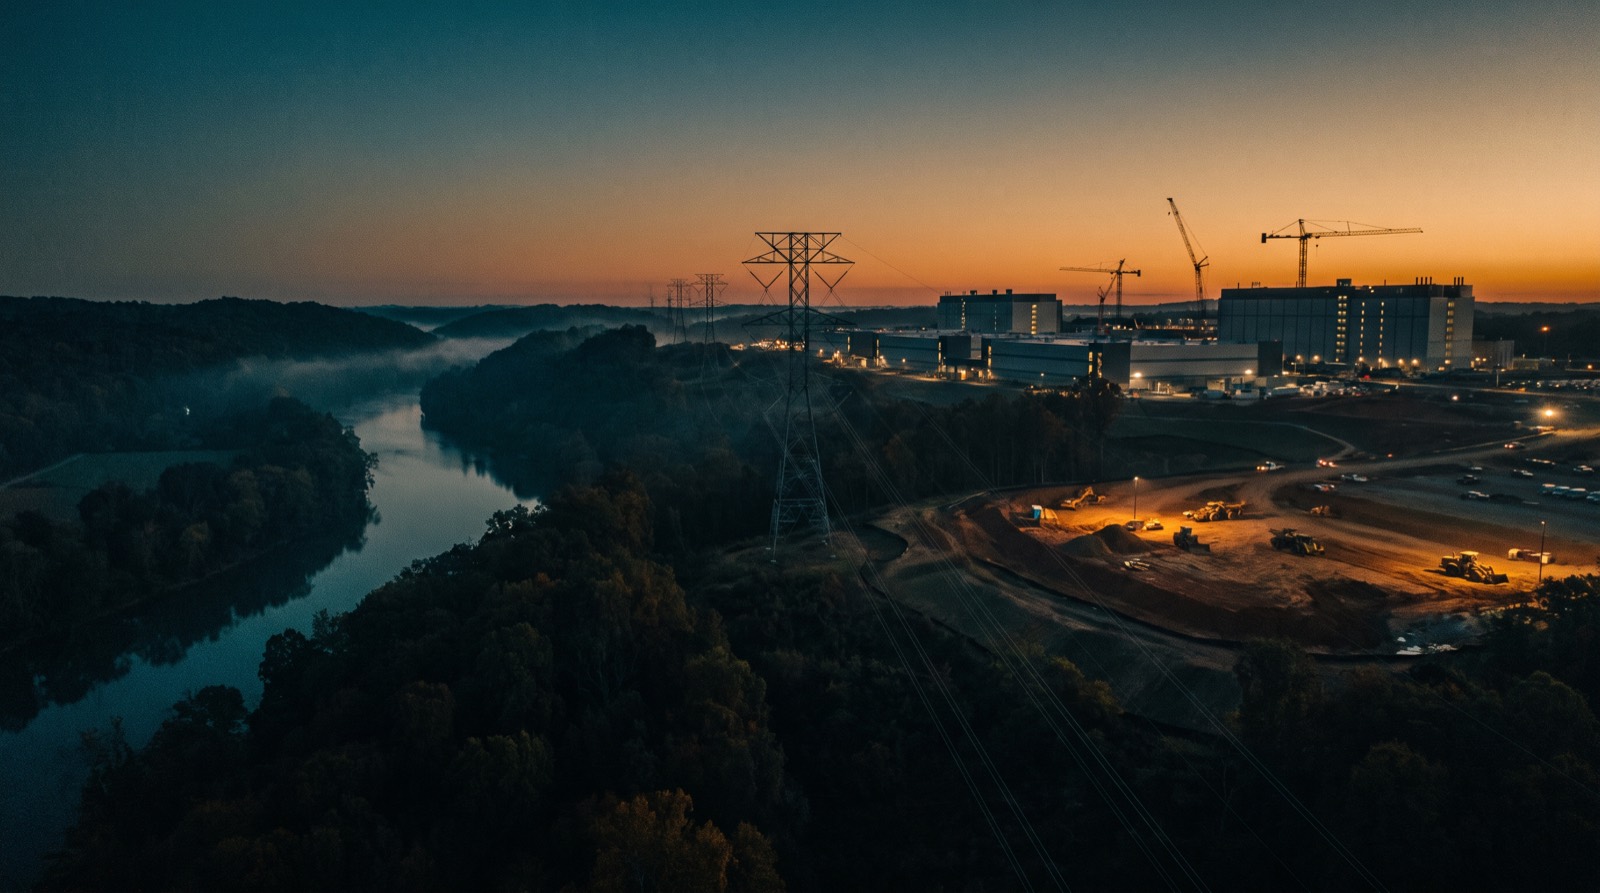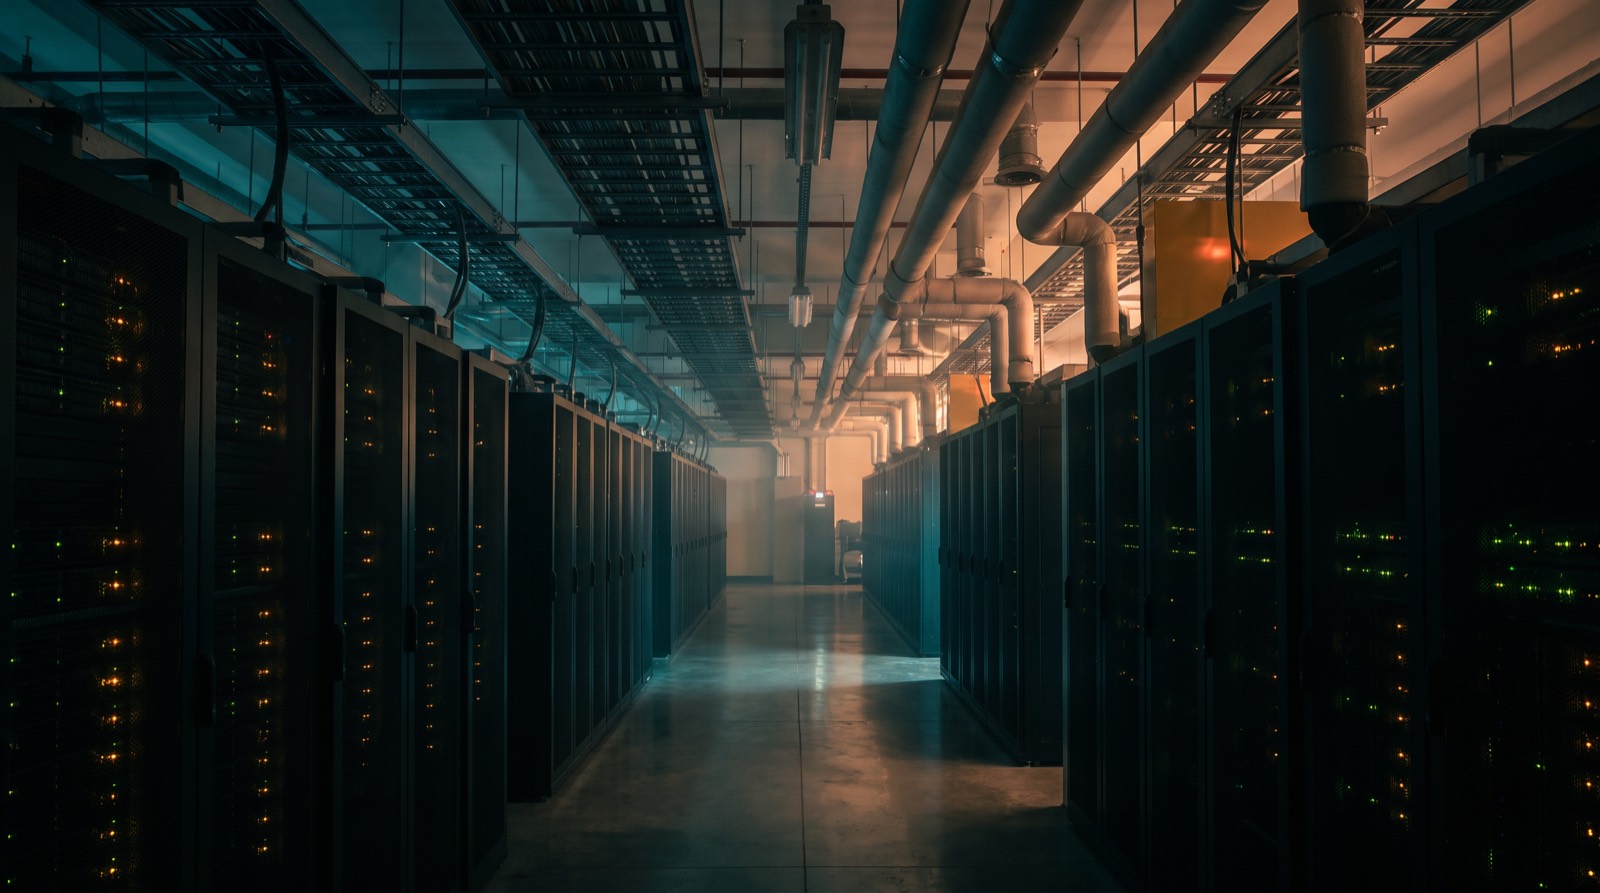
Walk an AI campus like Stargate Abilene from the fence line inward and you cross five machines nested inside each other.
1. The substation
High-voltage transmission arrives at an on-site substation — transformers the size of houses stepping 138–345 kV down toward distribution levels. This yard is often the schedule's critical path: large transformers carry multi-year lead times, and the interconnection agreement behind them may have taken longer than the buildings.
2. The electrical rooms
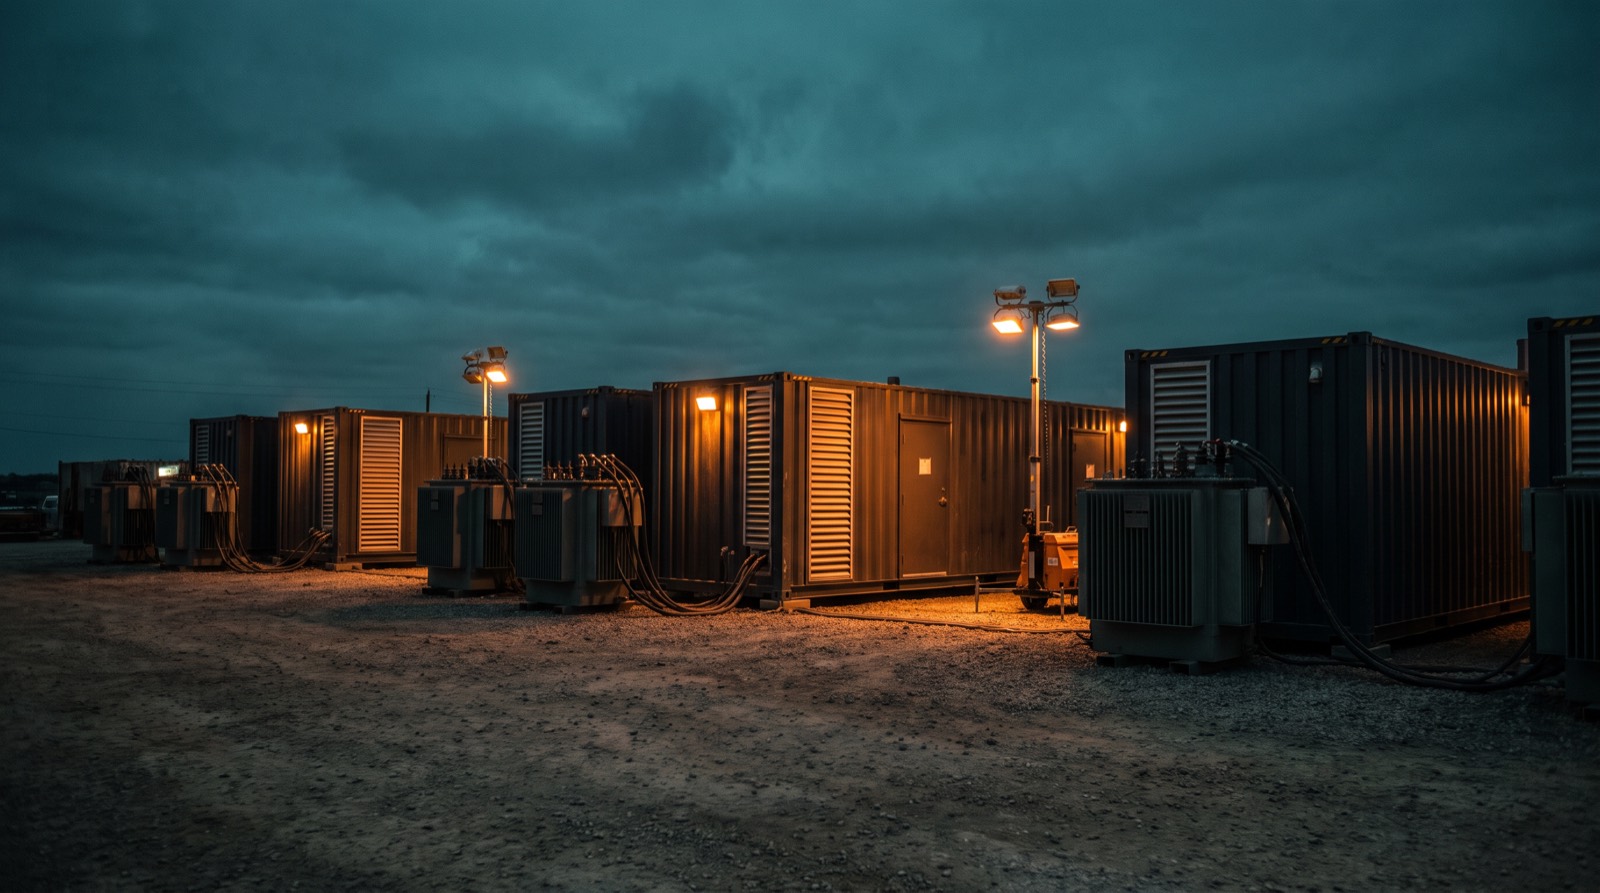
Inside, switchgear (Eaton, Schneider, ABB) routes power through uninterruptible supplies and busways down to the halls. Diesel or gas generators (Cummins, Caterpillar) idle outside as insurance; battery rooms bridge the seconds between grid loss and generator start. Rack voltages are climbing — NVIDIA's next-generation designs push 800-volt DC distribution to tame the copper needed for megawatt racks.
3. The halls
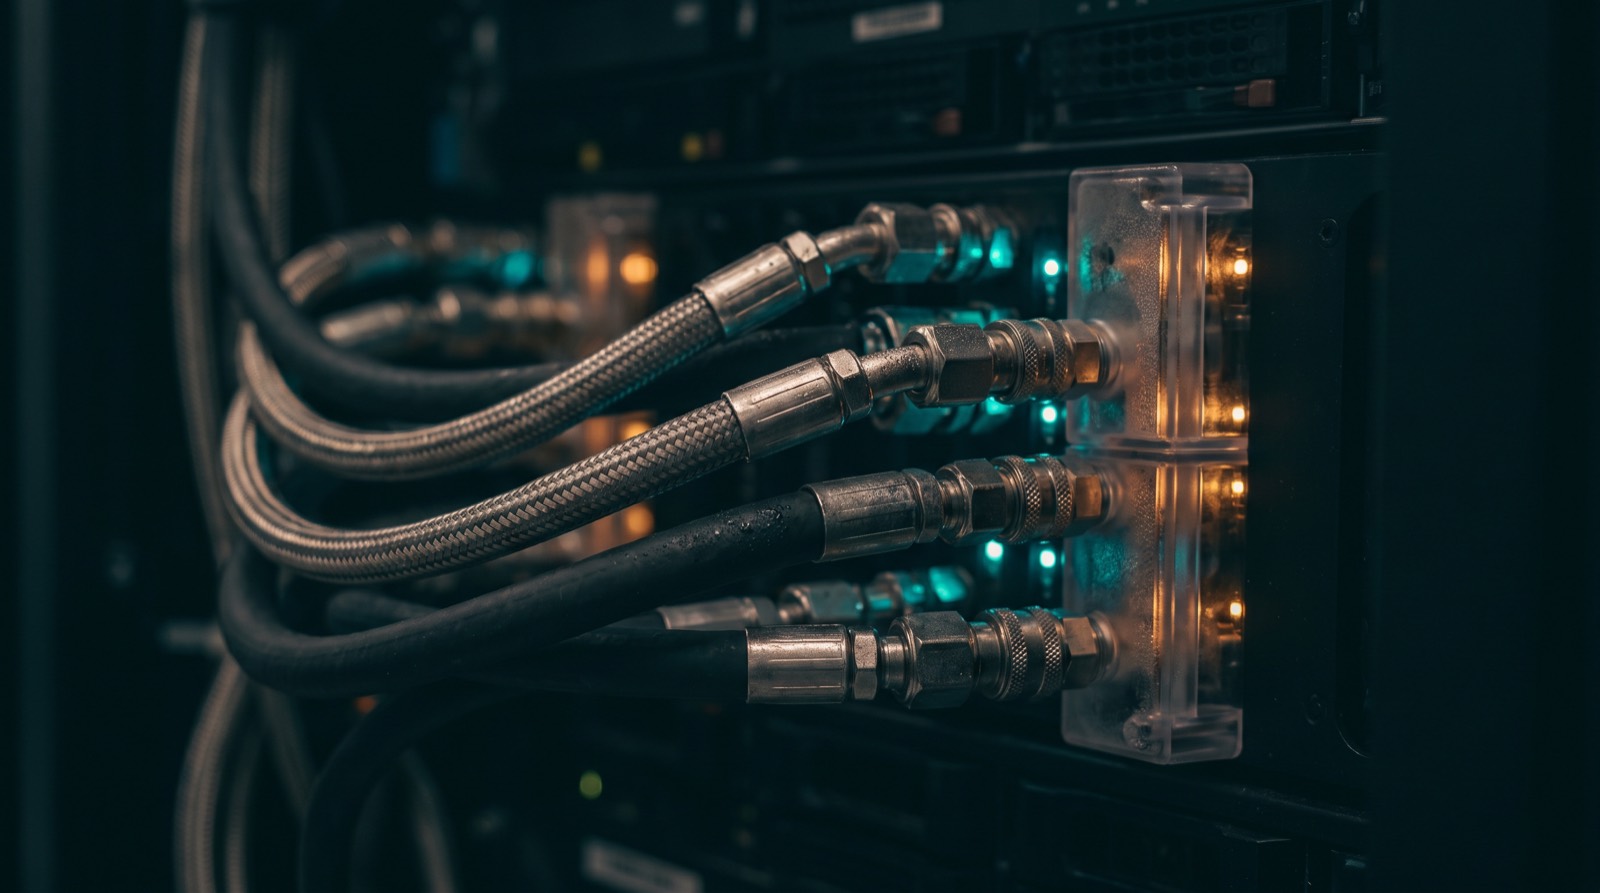
The data halls themselves are big, boring boxes engineered around density. A hyperscale hall holds hundreds of rows; an AI hall's rows are shorter but each rack is a monster — GB200 NVL72 racks draw ~120 kW, a hundred homes' worth each. Hot-aisle containment, overhead busway, and — new since 2024 — coolant manifolds running to every rack.
4. The cooling plant
Every watt in becomes heat out. Air handled the H100 era; Blackwell-class racks require direct liquid cooling: cold plates on every die, CDUs exchanging heat between the clean chip loop and the facility loop, then dry coolers, cooling towers or chillers rejecting it outdoors. Closed-loop designs like Fairwater's fill once and barely sip water thereafter — a direct answer to the community pushback water-hungry designs earned.
5. The machine in the machine
Finally the racks: GPU trays, NVLink spines, optical transceivers by the hundred thousand, and two networks — a front-end for users and storage, a back-end fabric (InfiniBand or AI Ethernet) that makes ten thousand GPUs act as one. Storage arrays feed training data; a control plane schedules it all (Slurm, Kubernetes).
The numbers that define the genre
Modern AI campuses are measured in hundreds of megawatts to gigawatts (see Trends for the reported league table), tens of billions of dollars, and — increasingly — in how fast they rose: Colossus went from empty factory to 100,000 GPUs in 122 days, and 'speed to power' is now the industry's favorite phrase.
 9